Hive OS. Установка, настройка, майнинг, команды, обновление. Полный туториал по системе.
Подробно разберем самую популярную систему для майнинга Hive OS. Hive OS представляет собой linux подобную операционную систему для майнинга на видеокартах и асиках. Выясним как правильно установить Hive OS, настроить систему для стабильной работы, настроить и разогнать видеокарты, как сделать кошелек и полетные листы для запуска майнинга. Изучим команды и возможности обновления. И самое главное, разберем основные причины проблем и ошибок которые встречаются при майнинге на HiveOS.
БАЗОВЫЙ УРОВЕНЬ, ДЛЯ НОВИЧКОВ
Регистрация в Hive OS
Hive OS промокод на 10$ при регистрации — InsidePC
В первую очередь нужно зарегистрироваться в HiveOS на официальном сайте. По данной ссылке с промо кодом «InsidePC», вы получите 10$ на счет, с которого сможете оплачивать систему. Регистрация в Hive OS ничем не отличает от регистрации в той же Rave OS, о которой мы писали в прошлой статье.
Если вы интересуетесь инвестированием в криптовалюту и хотите уберечься от частых ошибок и потери денег, рекомендую пройти БЕСПЛАТНЫЙ 3-х дневный марафон «Криптоинвестиции» от Школы Практического Инвестрирования. На марафоне вы узнаете актуальные стратегии и инструменты для инвестирования в крипту!
Когда вы попадете на сайт, нажмите на кнопку Sign In.

Регистрация в Hive OS
Если у вас есть промо код, нажмите Have a promo code?, нажмите и введите промо код InsidePC.

Промо код для получения 10$
После регистрации и входа в Hive OS, вы увидите веб интерфейс панели управления.

Панель управления Hive OS.
- Farms (Фермы) — ваши ферм.
- Wallets (Кошельки) — кошельки.
- Flight Sheets (Полетные листы) — полетные листы.
- Overclocking Templates (Шаблоны разгона) — шаблоны разгона.
- Notification (Уведомления) — уведомления.
- Your Funds (Ваши средства) — финансовые ведомости.
- Referrals (Рефералы) — рефералы.
- Account (Аккаунт) — аккаунт.
Как изменить язык системы
Рекомендуем использовать все профессиональные системы и сервисы на английском языке. Но если с английским совсем плохо, вы можете переключить на русский интерфейс. Для этого перейдите Аккаунты — Язык (язык будет сразу первой строчкой в настройках аккаунта).


Как запустить команды Hive
Изучив список команд, вы можете задать логичный вопрос: как на самом деле выполнить любую из них? Есть пять способов сделать это:
- С помощью значка «Выполнить команду» на панели;
- Через удаленную консоль Hive Shell или Teleconsole;
- Через веб-консоль ShellInABox;
- При подключении к ферме через IP-адрес. Вы можете сделать это с любым клиентом SSH (например, PuTTY);
- Через локальную консоль (например, клавиатуру или устройство).
3 маленьких ярлыка
Помимо команд, вы также можете использовать эти сочетания клавиш, чтобы сделать вашу майнинговую жизнь более удобной:
- Ctrl + C. Эта комбинация останавливает любую запущенную команду.
- Ctrl + A, D. Используйте эту команду, чтобы выйти из экрана (майнер или агент). Экран будет работать.
- Ctrl + A, Пробел или Ctrl + A, 1,2,3. С помощью этой комбинации вы можете легко переключаться между экранами, например, если у вас работает второй майнер.
Итак, теперь пришло время применить знания на практике — используйте эти команды, чтобы облегчить свою жизнь. И следите за обновлениями, мы поделимся множеством других полезных советов и хитростей в наших следующих статьях.
Настройки биос (bios) для материнской платы под Hive OS
- Настройте PCIe Link Speed на GEN2
- Отключите Internal Graphics (если это не нужно вам для монитора)
- Включите Above 4G Decoding
- Выключите CSM Support
- Убедитесь, что приоритет загрузки настроен правильно — устройство хранения, содержащее Hive, должно быть на первом месте
- (Опционально) Restore AC Power Loss (Power On)
Для ASUS B250 Mining Expert, PCIe Link Speed должна быть настроена в двух разных местах
- Advanced\PCH Configuration\PCI Express Configuration -> PCIe Speed -> Gen 2
- Advanced\System Agent (SA) Configuration\PEG Port Configuration -> PCIEX16_1 Link Speed -> Gen 2
И еще несколько рекомендаций касательно B250:
- Некоторые пользователи сообщают о лучшей совместимости с Gen 1 вместо Gen 2 на более крупных ригах
- Некоторые пользователи сообщают об улучшенной стабильности при пустом слоте x16_1
- Обновленный bios может помочь решить множество проблем с платой
Как это сделать, читайте в статье по настройке биоса материнской платы под майнинг.
Установка образа Hive OS на SSD, HDD, M.2 или флешку
Структура фермы в системе Hive OS
Для понимания правильной настройки ваших ферм в системе Hive OS, объясним иерархию объектов в ферме.
Ферма (Farms) — представьте это как объект, например гараж или комната в которой размещены ваши воркеры или риги (до ригов или воркеров мы еще дойдем). Благодаря объединению ригов в фермы, вы можете разделять их по геолокации, например если у вас риги в разных гаражах, офисах, квартирах, комнатах. Это больше нужно для тех, у кого много ферм и ригов.
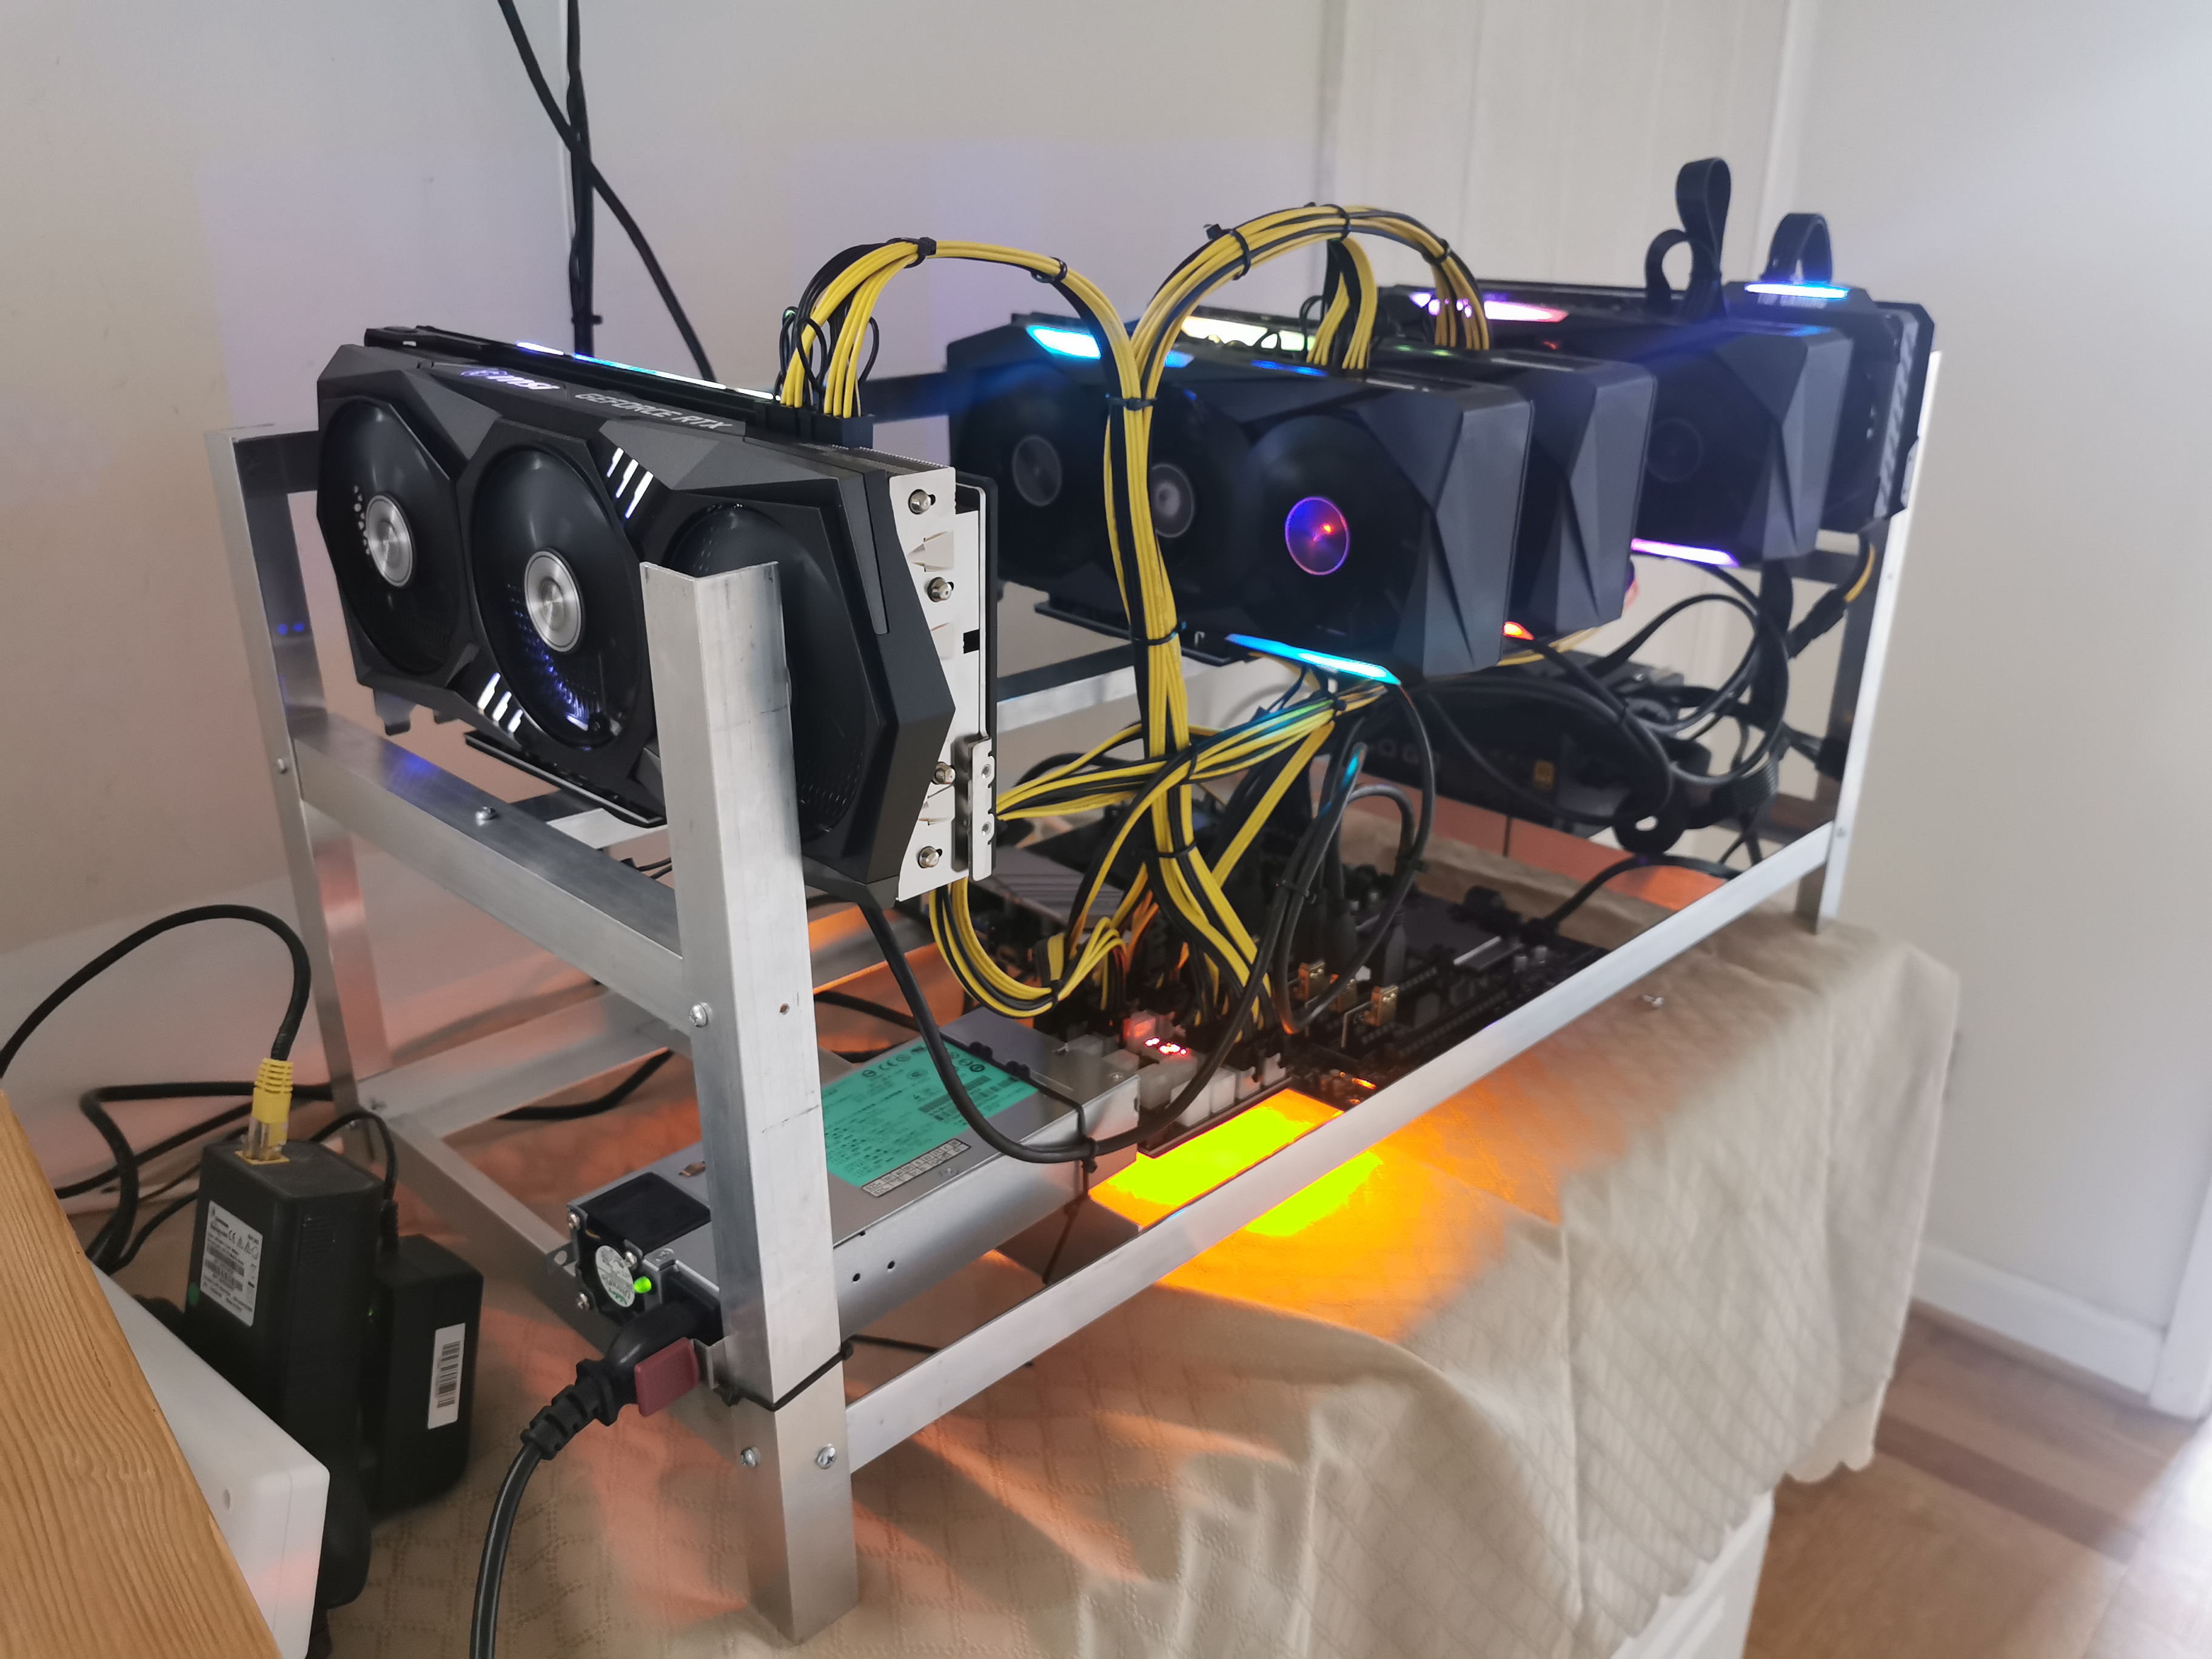
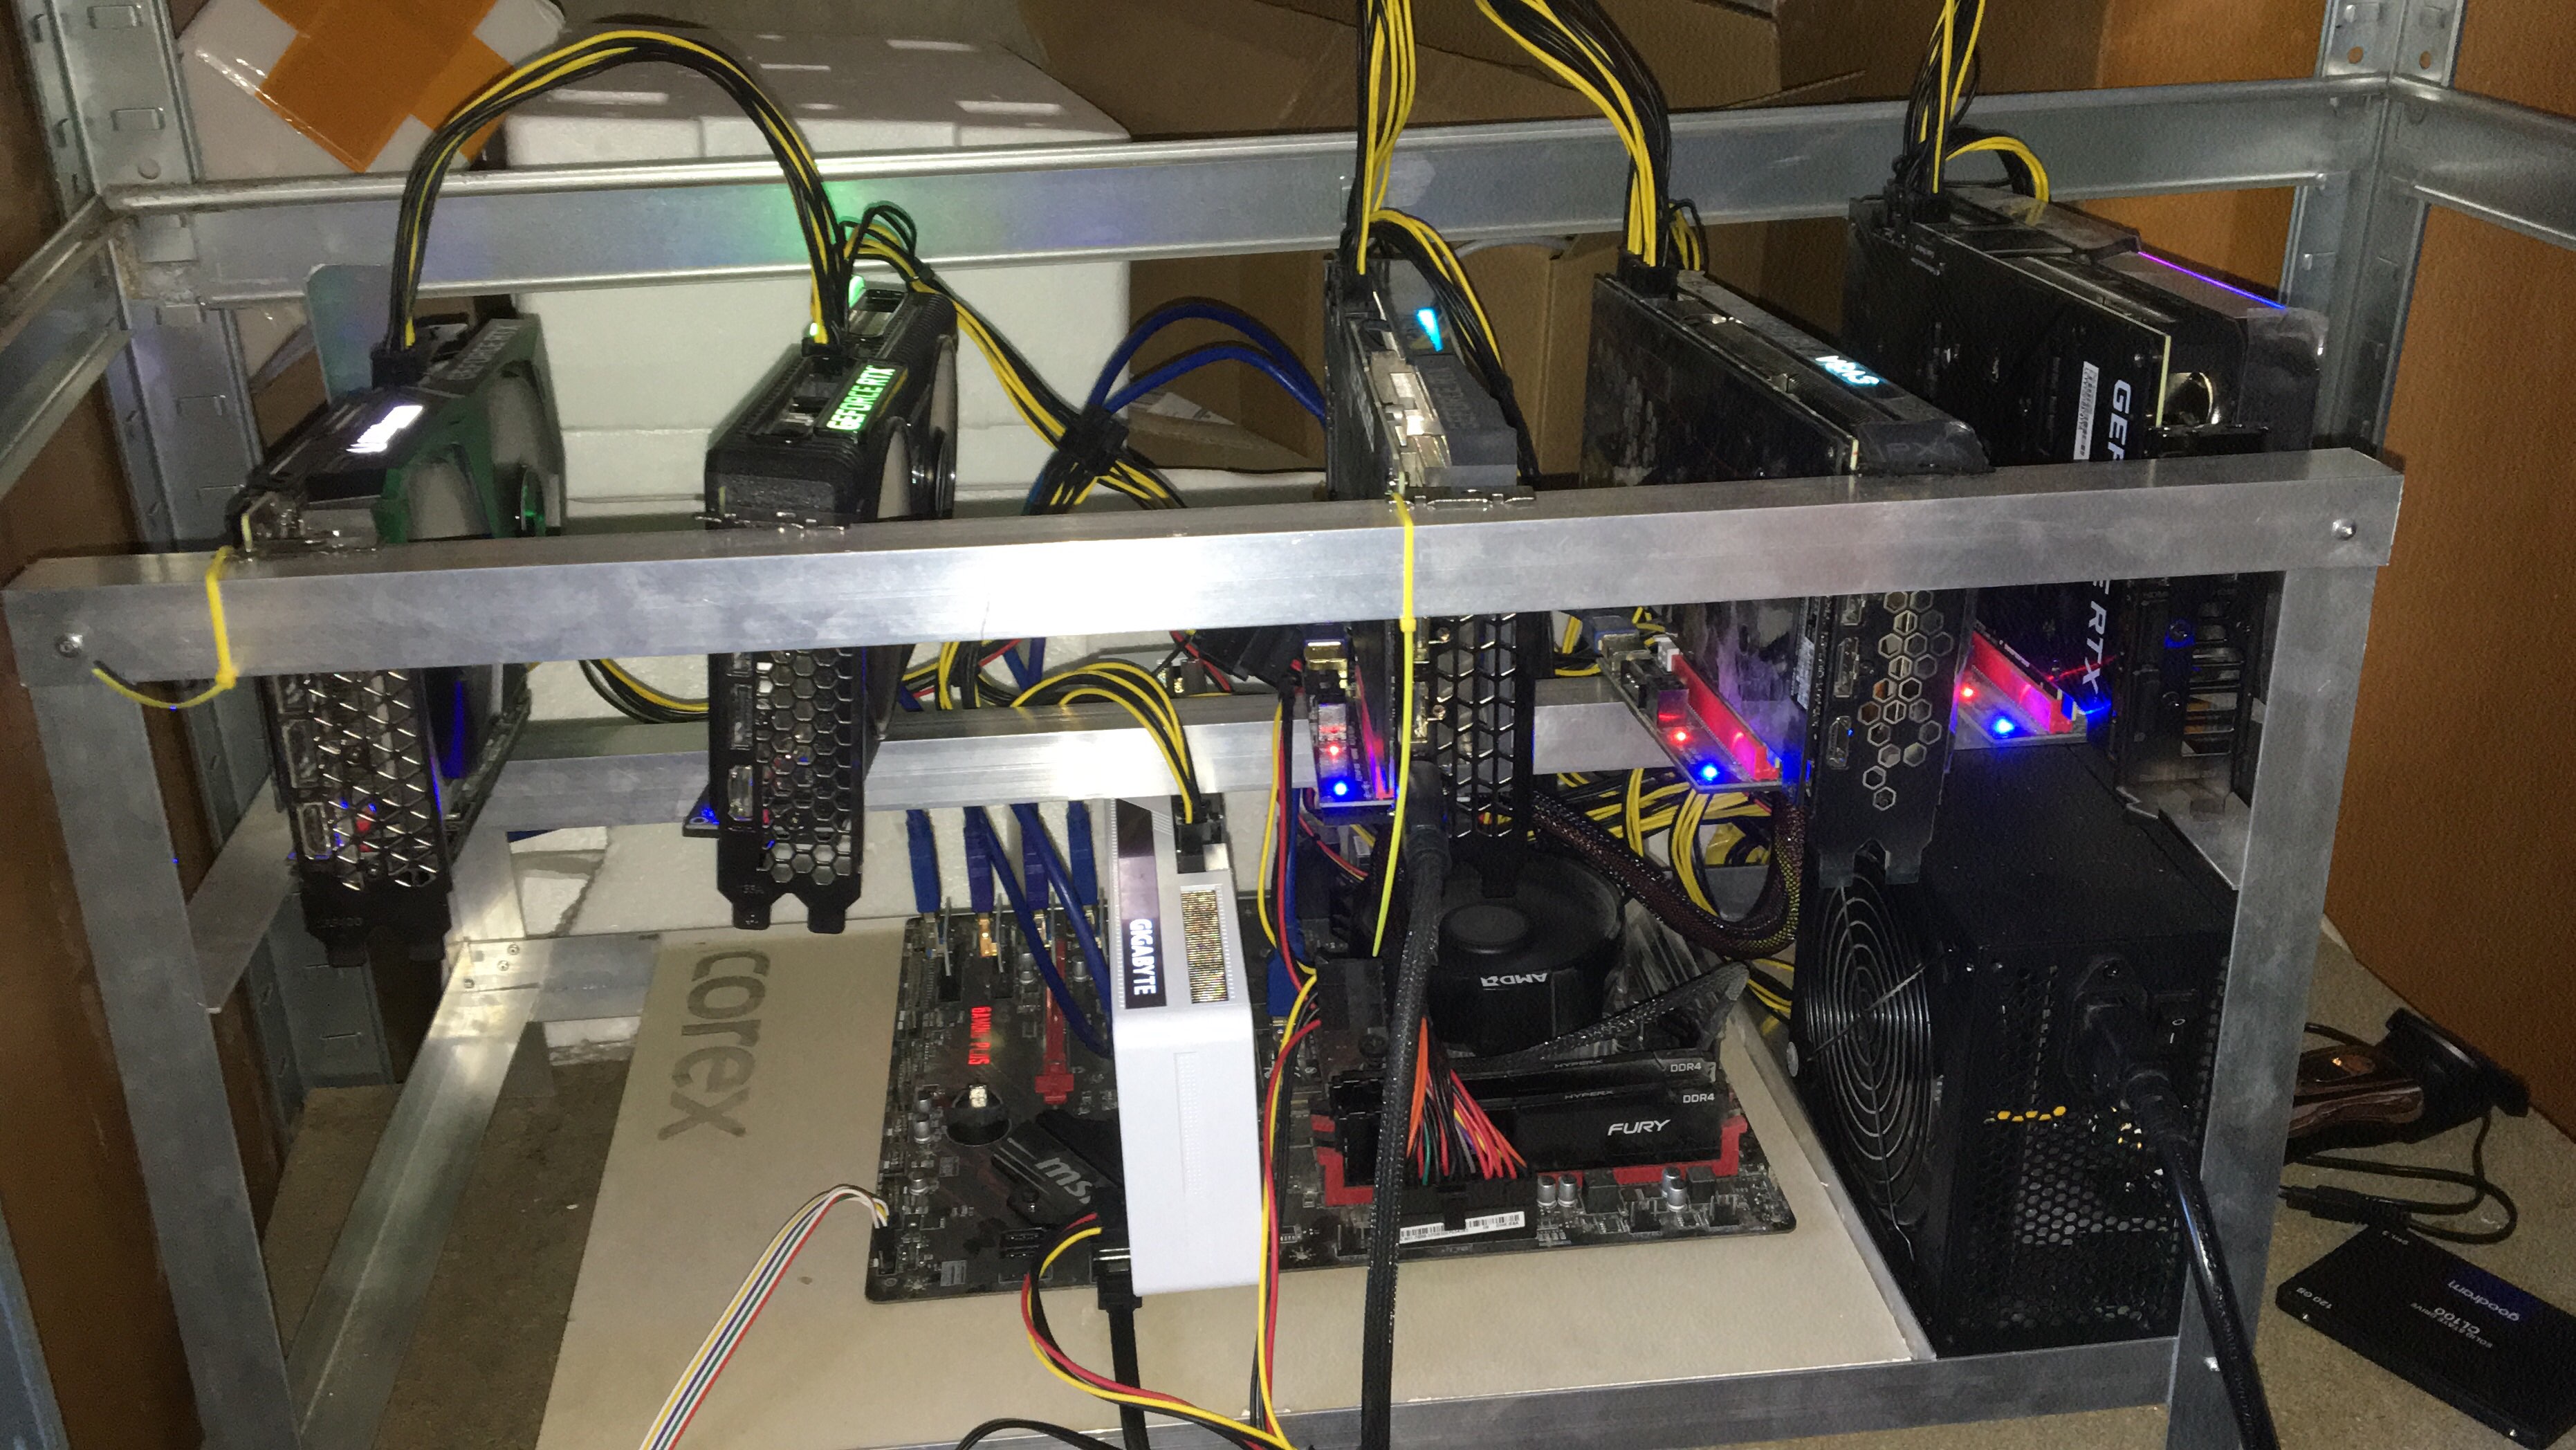
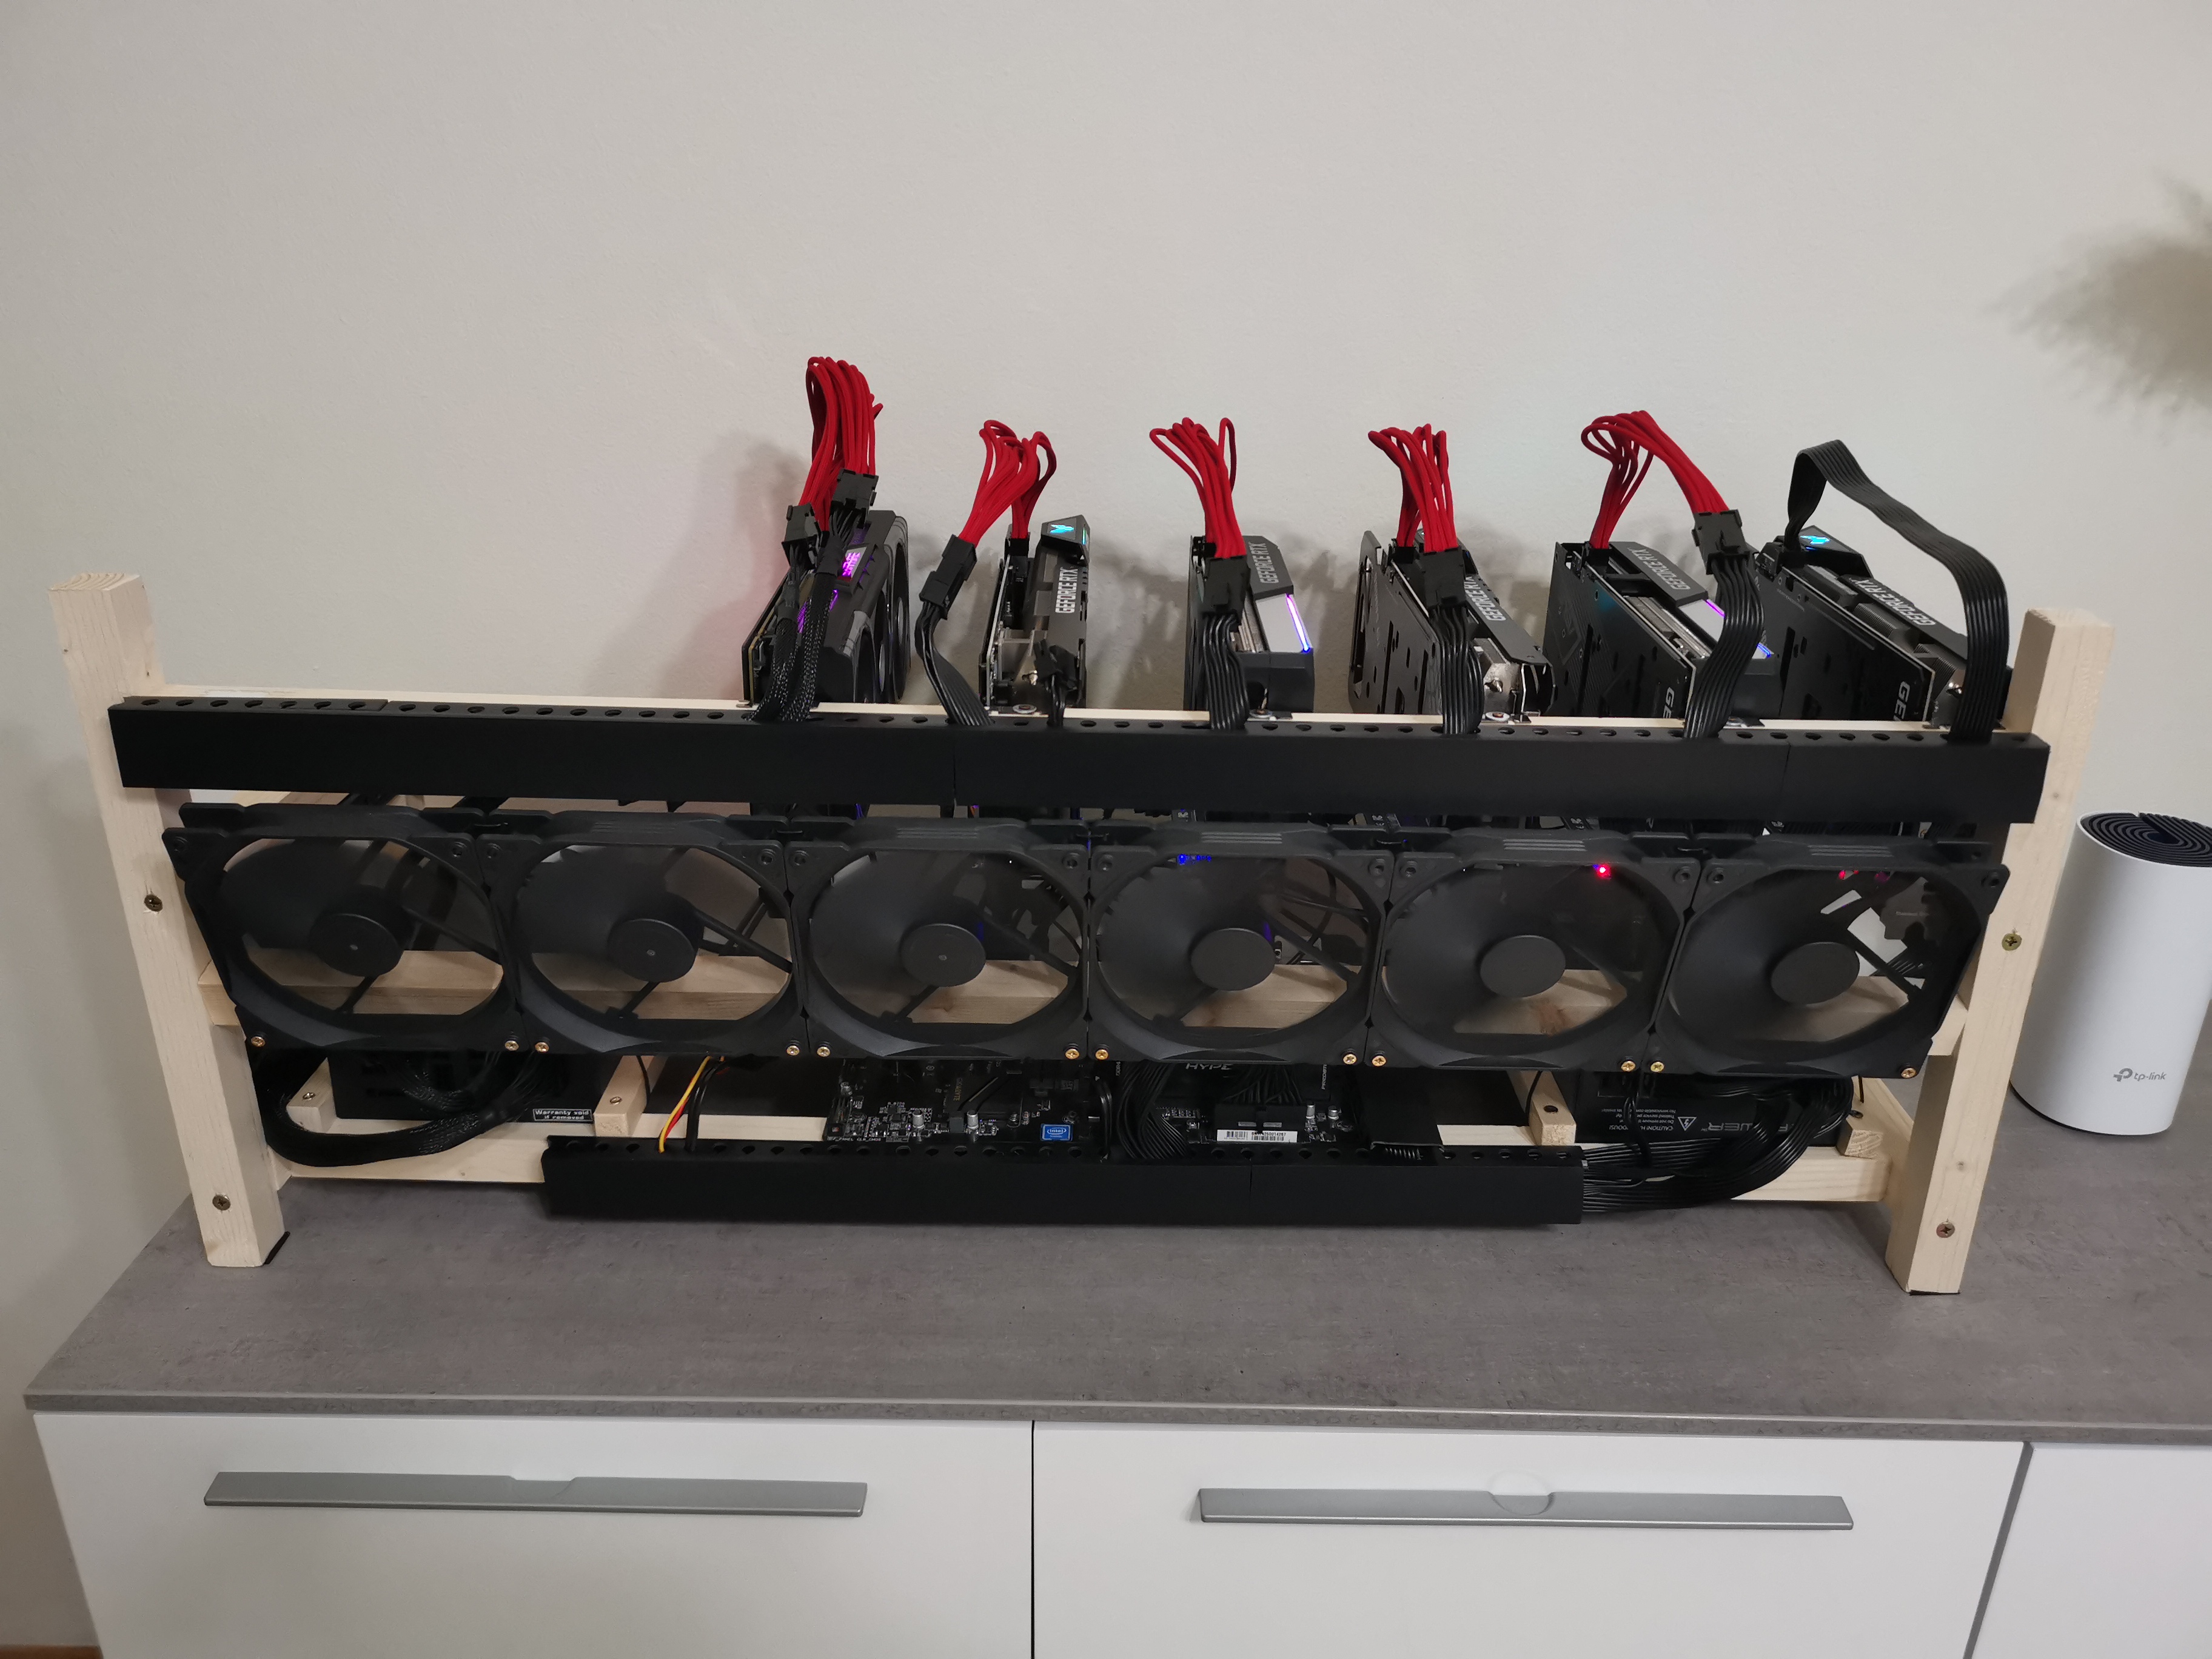
Воркер (Workers) — это непосредственно ваш риг. Т.е. материнская плата с процессором, блоком питания и видеокартами. В обычной жизни, это и называют фермой. Как собрать майнинг ферму, читайте на сайте.
Создаем ферму и воркер для подключения к образу
Прежде чем устанавливать Hive OS на носитель, нам нужно создать Ферму для привязки к системе которую будем записывать на флешку или SSD. Для этого заходим в веб интерфейс Hive OS.
Нас интересует вкладка Фермы. Справа вверху нажимаем + и добавляем новую ферму.

Создание новой фермы в Hive OS
- Имя — имя фермы.
- Часовой пояс — часовой пояс. Указывайте тот часовой пояс где находится ферма, это необходимо для отображения правильных временных кодов.
- Автотэги — полезная вещь, если у вас много ферм и много ригов. Автоматически помечает тэгами GPU и ASIC.
- Hiveon Pool Charging — данная опция позволят вам не платить за фермы 3$ в месяц, а оплачивать процент с пула. Мы не рекомендуем использовать Hiveon Pool, он не плохой, просто есть гораздо лучше пулы для майнинга эфира. Например Binance.
После создания фермы, вас перебросит на вкладку воркер. Справа вверху будет иконка «+» через которую вы создаете новый воркер.

Создание воркера в HiveOS
- Платформа — выбираете GPU если у вас видеокарты, или ASIC если асики.
- Имя — имя воркера.
- Пароль — пароль воркера, для предоставления доступа.
- Теги — можете задать теги для удобства.
- Описание — описание воркера для себя.
После нажатие на кнопку «Добавить», вы попадаете в настройки рига или воркера.

FARM_HASH and rig.conf
Тут нам нужен FARM_HASH. Это код который нужно будет вставить в образ Hive OS после записи этого образа. Либо вы можете в этом окне сказать rig.conf с уже прописанным FARM_HASH и скопировать в систему после создания образа. Мы рассмотрим оба варианта.
Устанавливаем образ Hive OS
Для записи образа Hive OS, проще всего воспользоваться программой HDD Raw Copy Tool. Мы покажем процесс установки на ней, но вы можете воспользоваться программой Etcher, она более современная.
Запускаем HDD Raw Copy Tool и в поле File выбираем образ Hive OS (Please select SOURCE).

HDD Raw Copy Tool для записи Hive OS
Нажимаем Continue и выбираем диск или флешку на которую будем записывать образ в поле ATA (Please select TARGET).

HDD Raw Copy Tool для записи Hive OS
Нажимаем Сontinue и подтверждаем запись.
После записи у вас появиться еще одни жесткий диск с файлами и именем Hive OS.
Вам нужно будет зайти в него и скопировать туда файл rig.conf, который вы скачали на предыдущем шаге. Либо найти там файл rig-config-example.txt и вставить в него FARM_HASH с воркера в поле FARM_HASH и сохранить этот файл с именем rig.conf.
После этого, нужно будет подключить образ к материнской плате фермы. К этому моменту вы уже должны были настроить материнскую плату фермы, ссылки выше на статьи и собрать и подключить ферму.
Установка GPU
Запись образа диска
Проверенные материнские платы для майнинга на 2021 год
Вам нужно будет записать образ Hive OS на SSD. Хотя многие пользователи предпочитают USB-накопители, мы рекомендуем SSD. Начните с извлечения образа из .zip файла, и затем запишите файл .img file на накопитель.
Пользователи Windows могут записать образ при помощи HDD Raw Copy Tool, Win32 Disk Imager, Rufus или Etcher.
Пользователи MacOS или Linux могут легко сделать это, используя Etcher или некоторые другие программы.
Когда образ будет записан, вы обнаружите в вашей системе недавно созданный диск, где вы сможете предварительно настроить ваш воркер при помощи Farm Hash или же используя его ID и пароль. Найдите на диске HIVE и откройте его текстовым редактором. Вы можете использовать встроенные текстовые редакторы на Windows, MacOS и Linux или же загрузить бесплатную альтернативу. Например, Notepad++ для Windows или Sublime Text для MacOS и Linux.
Теперь выберите одну из двух опций:
Опциональный шаг — Farm Hash
Когда копирование образа завершится, вы можете перейти в ваш диск в Windows, Linux или Mac, и найти файл в корневой папке. Он выглядит вот так:

Содержимое файла rig-config-example.txt
Введите свой Farm Hash в поле , скопировав значение из вкладки настроек (Settings). Теперь поле должно выглядеть подобным образом:
В данном случае, неот необходимости настраивать RIGID или RIGPASSWD. Просто сохраните ваш файл с настройками и переименуйте его в . Продолжите, завершив установку образа, и запустите ваш воркер. Он автоматически подключится к панели управления.
Опциональный шаг — ручная настройка
Когда копирование образа завершится, вы можете перейти в ваш диск в Windows, Linux или Mac, и найти файл в корневой папке. Он выглядит вот так:

Содержимое файла rig-config-example.txt
Найдите и заполните эти два поля:
Вот и все, просто сохраните ваш файл с настройками и переименуйте его в . Продолжите, завершив установку образа, и запустите ваш воркер. Он автоматически подключится к панели управления.
Запуск майнинга на Hive OS
Для запуска майнинга нужно помимо уже сделанного, создать кошелек и полетный лист.
Создание кошелька в Hive OS (куда мы будем майнить)
Создаем кошелек в Hive OS. В web интерфейсе переходим во вкладку «Кошельки» и нажимаем кнопку «Добавить кошелек». Лучше всего создавать разные кошельки для разных монет, особенно, если вы планируете майнить различные монеты и переключаться между ними. При выборе монеты в Полетных листах, выбор кошельков будет ограничен этой монетой.

Создание кошелька на Hive OS
- Монета — ETH. Кошелек какой монеты мы создаем.
- Адрес — адрес кошелька или аккаунта на Binance Pool. Мы рассматриваем Binance Pool, т.к. это лучший пул для майнинга эфира на сегодня. Пройти регистрацию на Бинанс пуле можно по этой ссылке.
- Имя -Имя кошелька.
- Источник — В нашем случае binance.
- binance Ключ API — сюда можете вставить API кошелька и получать баланс через Hive OS (по желанию, считаем, что это не обязательная функция).
- Получить баланс кошелька — включаете функцию вывода баланса кошелька пула.
Кошелек создан. Переходим к созданию полетного листа.
Создания полетного листа
Полетный лист позволяет переключаться мгновенно между кошелками, пулами, монетами. Это по сути файлы конфигурации вашего воркера.
Для создания полетного листа в Hive OS переходим во вкладку «Полетные листы (Flight Sheets)».

Создание полетного листа в Hive OS
- Монета — выбираем монету. В зависимости от выбранной монеты, будут доступны только кошелки для этой монеты.
- Кошелек — выбираем кошелек который мы создали ранее.
- Пул — выбираем пул на который будем майнить. А так же сервера пула. Если вы выбрали несколько серверов, то воркер будет присоединятся в порядке очереди к каждому следующему если предыдущий перестал работать. Лучше выбрать 2-3 сервера.
- Майнер — выбираем майнер. Рекомендуем использовать NBMiner. При выборе майнера, будет манятся текст Nvidia, AMD или CPU. В зависимости от того с какими картами работает майнер, или процессорами.
- Имя — вводим имя полетного листа.
Запускаем майнинг на Hive OS
Мы сделали все необходимое для запуска майнинга. Выбираем нашу ферму, выбираем наш воркер. Когда вы будете в воркере и будете видеть кол-во карт, перейдите в «Полетные листы».

Запускаем майнинга на Hive OS
Нажимаем справа на ракете и запускаем майнинг.
Поздравляем, вы запустили майнинг на Hive OS. Подождите пару минут пока майнер запустить процесс майнинга.
Как зарегистрироваться и на сайте hiveos.farm, создать учетную запись и кошелек?
Лучшие пулы для майнинга криптовалют 2021
Для использования OS Хайв необходимо пройти процедуру регистрации и создать учетную запись, защищенную паролем и, желательно, двухфакторной аутентификацией.
Для регистрации Hive необходимо ввести информацию об имени, желаемый логин, электронный почтовый адрес, выбрать нужную часовую зону и создать пароль аккаунта.
После регистрации появится окно, в котором отображается логин, статус ферм и текущий баланс на счету пользователя (в данном случае одна ферма):

Для обеспечения защиты от взлома желательно установить двухфакторную аутентификацию через меню «аккаунт», где нужно сдвинуть вправо соответствующий ползунок:
Для создания воркера (ID рига) нажимают на поле фермы в основном окне своего аккаунта, после чего появится окно, которое позволяет:

- создавать воркеры – идентификаторы и пароли для каждого рига;
- отслеживать статистику работы;
- создавать кошельки, содержащие информацию о адресах куда будет перечисляться добытая при майнинге криптовалюта;
- создавать полетные листы, которые содержат конфигурацию для майнинга, которая может применяться на любом риге;
- создавать профили разгона для разных алгоритмов и ригов;
- во вкладке активность отслеживать действия с аккаунтом;
- во вкладке доступ отслеживать действия по аутентификации в аккаунте других пользователей;
- с помощью биллинга работать с платежами для аккаунта (необходимо при управлении более, чем тремя ригами);
- настраивать конфигурацию личного кабинета.
Если вы забыли hive os пароль ничего страшного, введите адрес электронной почты и вам предоставят токен восстановления и ссылку для смены пароля.
Более серьезной проблемой будет утеря кода двухфакторной аутентификации, обязательно и сохраните на бумажном или электронном носителе код подключения 2FA.
Для создания воркера в окне фермы нажимают плюс в белом квадрате:

В раскрывающемся списке выбирают добавление воркера:
Во всплывающем окне конфигурируют новый воркер в соответствии с ригом, к которому он будет относится:

После этого в аккаунте появится окно с ID рига, паролем и данными FARM_HASH:

ID рига и пароль к нему нужно переписать, они понадобятся для его активации при первой загрузке.
Для дальнейшей работы с ригом необходимо создать кошельки, которые будут сохранять информацию об адресах, на которые будут перечисляться монеты при майнинге. Для их создания нажимают на название фермы (слева вверху персональной страницы https://the.hiveos.farm/farms) и выбирают меню кошельки. На открывшейся странице активируют кнопку добавить кошелек:

В появившемся окне из раскрывающегося списка выбирают название монеты, вводят соответствующий ей адрес своего кошелька и дают ему название (в данном случае — Monero).

Все созданные кошельки можно проконтролировать и, при необходимости, отредактировать в меню кошельков каждой фермы.
Для настройки майнинга на конкретный пул используется меню полетных листов (они выполняют роль BAT-файлов в Windows), в котором из выпадающих списков выбираются:
- алгоритм майнинга (монета):
- нужный кошелек (адрес, куда будут перечисляться средства от майнинга);
- выбирается пул и наиболее близко расположенные по географическому признаку (пингу) сервера;
- программа-майнер;
- задается имя выбранной конфигурации (полетного листа).

После настройки конфигурации нажимают кнопку создания полетного листа в правой нижней части окна настроек рига.
Настройка аккаунта, фермы и воркера в Hive OS
Настройка аккаунта в Hive OS (Account Profile Settings)
Что бы попасть на страницу настроек аккаунта, с главной страницы Hive OS перейдите во вкладку Аккаунт (Account).
- Language (Язык) — изменения языка системы.
- Profile (Профиль) — логин, имя в системе и email.
- Notifications (Уведомления) — настройка уведомлений в Telegram или Discort.
- Password (Пароль) — изменение пароля.
- Two-factor Authentication (Двухфакторная аутентификация (2FA)) — подключение двухфакторной аутентификации. Дополнительный уровень безопасности.
- White List (Белый список) — белый список ip адресов. Не используйте это на динамическом IP адресе (если ваш интернет-провайдер меняет его или вы заходите через мобильную сеть)
- Authentication Tokens (Токены аутентификации) — Вы можете управлять своими персональными API токенами. Вы можете создать новый для своего стороннего приложения. Или удалить подозрительную сессию. Тут можете увидеть текущие сессии и закрыть их при необходимости. API документация тут.
- Bio (Биография) — тут можно ввести дополнительную информацию о вас: телефон, telegram, skype, информация о компании, часовой пояс.
- Advanced Settings (Расширенные настройки) — Delete account (Удалить аккаунт) — удаления аккаунта.
Настройка фермы в Hive OS
Что бы попасть на страницу настроек фермы, нужно выбрать нужную ферму, под каждую ферму свои настройки, и нажать на ссылку «Settings (Настройки)». Какие настройки фермы доступны в Hive OS?
- Name (Имя) — задаем имя фермы. Не на что не влияет.
- Farm Hash — Farm Hash используется для подключения воркера к ферме без предварительного создания в веб.Просто установите его в rig.conf перед первым запуском. Мы не расматриваем такой способ подключения, т.к. есть более удобные, описанные выше.
- ASIC configuration files (Файлы конфигурации ASIC) — Генератор файлов привязки ASIC. Настройка для асиков.
- Tags (Теги) — добавление своих тегов для маркирования воркеров.
- Timezone (Часовой пояс) — часовой пояс фермы.
- Notifications (Уведомления) — возможность настройки уведомлений для фермы. Т.е. они будут распространятся на все воркеры в ферме.
- Electricity price, $/kWh (Цена электроэнергии, $/кВт*ч) — Цена электроэнергии для точных подсчетов потребления. Вы можете установить валюту, добавив ее после пробела. Например: 5.47 RUB.
- Hardware power consumption, watts (Потребляемая мощность, Вт) — Значение по умолчанию для всех воркеров фермы. Может быть изменен для воркера отдельно.
- Power supply unit efficiency, % (КПД блока питания,%) — КПД блока питания для более точных подсчетов потребления. Значение по умолчанию для всех воркеров фермы. Может быть изменен для конкретного воркера.
- Advanced Settings (Расширенные настройки)
- Packages repository server mirror URL (Адрес зеркала сервера хранилища пакетов) — данная настройка позволяет указать локальные пакеты для обновления. Это позволит сохранить трафик и увеличить скорость обновления. Рекомендуется только для тех пользователей, которые понимают что это и точно знают зачем им это.
- Transfer farm (Передача фермы) — Передача фермы другому пользователю. Введите логин существующего пользователя, который будет новым владельцем фермы. Тут все должно быть понятно, передача фермы другому владельцу.
- Remove Farm (Удалить ферму) — Удаление фермы.
Настройка воркера в Hive OS
Для настройки воркера, нужно войти в нужный воркер и перейти во вкладку «Settings (Настройки)». Какие настройки воркера доступны в Hive OS?
- ID — уникальный идентификатор воркера. Так же в строчке с ID есть ссылка на готовый файл rig.conf.
- Farm hash — Farm hash вашего воркера который прописывается в файле rig.conf.
- Name (Имя) — имя воркера.
- Description (Описание) — описание воркера.
- Tags (Теги) — тэги для удобства сортировки видеокарт в воркере по типам памяти, моделям и т.д.
- Password (Пароль) — пароль воркера.
- Resend all configs (Переслать все настройки) — выгрузка настроек воркета для импорта в другую ферму.
- Cards/Boards Quantity (Количество карт/плат) — данный параметр увеличивается автоматически. Но можно его менять и вручную.
- GUI on boot (Отключить GUI при загрузке) — не запускать Х-сервер, только консоль, для Nvidia не будет разгона.
- Maintenance mode (Режим технического обслуживания) — включить режим обслуживания (не запускать майнер и сторожевой таймер при загрузке)
- Push interval (Интервал сброса данных) — Интервал в секундах между отправкой статистики на сервер. По умолчанию 10 секунд. Обратите внимание, что конфиги и команды будут обрабатываться воркеров с одинаковым интервалом.
- Power cycle — когда эта опция включена, все перезагрузки будут выполняться как выключить и включить через 30 секунд.
- DoH — DNS поверх HTTPS (DoH) — протокол для выполнения разрешения DNS по протоколу HTTPS. Использование DoH повышает конфиденциальность и безопасность пользователей путём предотвращения перехвата и манипулирования данными DNS.
- Miner delay (Задержка старта майнера) — задержка в секундах до запуска майнера при включении воркера.
- Hardware power consumption, watts (Потребляемая мощность, Вт) — вы можете установить энергопотребление «тушки» для более точного расчета энергопотребления.
- Power supply unit efficiency, % (КПД блока питания,%) — вы можете установить КПД блока питания для более точного расчета потребляемой мощности.
- Mirror Select (Выбор зеркала) — если у вас возникли проблемы с подключением к Hive сервера от вашего воркера и часто возникают ложные события не в сети / в сети, вы можете попробовать выбрать другой URL-адрес для подключения к серверу. Иногда возникает проблема с брандмауэром (ваш собственный или ISP) и смена порта может помочь.
- VPN — подключение VPN.
- Advanced Settings (Расширенные настройки)
- Transfer Worker (Перенос воркера) — перенести воркера на другую ферму. Кошелек не переносится с воркером. Пожалуйста, примените кошелек с другой фермы после того как перемещение будет завершено.
- Worker Activation/Deactivation (Активация воркера) — активация и деактивация воркера.
- Remove Worker (Удалить воркера) — удаление воркера.
Как управлять ригом, основные нюансы после настройки
Работа с ригом после активации осуществляется через веб-интерфейс в личном кабинете пользователя на сайте Hive OS. Управление осуществляется путем нажатия на соответствующий ригу воркер. В верхней части окна воркера выведены основные кнопки управления:

Они позволяют производить следующие действия:
- управлять питанием:
- задавать вручную сетевые параметры для связи с ригом, в том числе осуществлять работу через VPN;
- выполнять команды Linux;
- запускать майнинг;
- работать с консолью рига;
- работать с майнером;
- использовать вотчдог;
- управлять температурным режимом и вентиляторами.
Включение майнинга производится с помощью нажатия на кнопку ракеты, после чего можно будет выбрать нужный полетный лист:

После его выбора нажимают кнопку применить, и риг начнет майнинг в соответствии с заданной конфигурацией:

В меню рига будет отображаться информация о его состоянии, включая информацию о каждой видеокарте, их температурах, хешрейте, стабильности работы и другие важные параметры:

Если вы сделали апгрейд оборудования, но не знаете, как удалить воркера на хайв ос, или вас по каким-то причинам не устраивает работа в OS, зайдите в свой аккаунт. Двойным щелчком по названию фермы откройте настройки воркеров. Кнопка удаления оборудования находится в правом углу рядом с именем фермы.

Система запросит подтверждение серьезности ваших намерений, наберите yes и нажмите подтвердить.

Готово воркер удален, можно создавать новую конфигурацию оборудования. Для удаления фермы полностью, перейдите расширенные настройки, кнопка «Удалить ферму» находится внизу, процесс происходит аналогично удалению воркера.
Учтите, после удаления фермы, будут ликвидированы все данные о настройках видеокарт, полетных листах и кошельках выбранных вами монет. Придется все создавать заново.

Для настройки Hive OS wifi необходимо ввести команду wifi и прописать ssid и pass для подключения к роутеру. В случае возникновения проблем, открыть флэшку с хайвом через Windows и отыскать файл конфигурации, для внесения имени и пароля беспроводной сети. Если система отображает wifi-адаптер, как одно из подключенных usb-устройств, не классифицируя его по типу назначения, значит, ферма не в сети. Скорее всего, вам вообще не удастся запустить майнинг, даже если на виндовс все прекрасно работало. Операционные системы линукс, иногда не дружат с некоторыми wifi-адаптерами и тут ничего не поделаешь. Кабельное соединение все-таки надежнее, майнить на виндовс или Hive OS wifi, не очень хорошая идея.
Разгон видеокарт в Hive OS
Разгон видеокарт от NVIDIA
Шаг 1 — Заходим в ферму. Во вкладке Farms(Фермы), выбираем нужную ферму.

Hive OS — Farms
Шаг 2 — Заходим на нужный риг. Выбираем риг в котором стоят карты которые мы будем разгонять.

Workers в Hive OS
Шаг 3 — выбираем нужную карту, все карты, определенные карты. Выбираем нужную карту и нажимаем на значок спидометра. Можно выбрать этот значок напротив конкретной карты, либо выбрать значок спидометра с надписью ALL. Тут задаются настройки разгона для всех карт Nvidia или AMD. Если у вас несколько одинаковых карт в риге, можно применить разгон сразу ко всем картам. Так же можно разогнать только определенные карты, об этом ниже.
Разгон RTX 3070 в HiveOS
Шаг 4 — Устанавливаем параметры разгона. Окно настроек для видеокарт от AMD отличается от карт для NVIDIA и имеет свои нюансы:

Оптимальный разгон и настройки RTX 3070 в Hive OS
- В поле +Core Clock Mhz (+Частота ядра Mhz) — указываем частоту в Mhz которую вы добавляете или снижаете от базовой.
- В поле Memory Clock, Mhz (Частота памяти, Mhz) — указываем значение частоты видео памяти. Частота видео памяти указывается умноженная на 2. Т.е. если вам нужно увеличить частоту на 1000 MHz, вбиваете 2000 Mhz. Это особенности разгона на Hive OS и Rave OS.
- В поле Вент., % (0 авто) — частота вращения вентиляторов. Оставляете 0 если у вас стоит Auto Fan.
- Предел потребления, W — указываете предел потребления карты в ваттах.
- Задержка в секундах перед применением разгона — указываете в секундах задержку начала разгона после того, как карта запустилась. Иногда это помогает от отвала видеокарты.
- Выключить подсветку (может не работать на некоторых картах) — очень редко работает.
- OhGodAnETHlargementPill — включает так называемую таблетку (Pill), используется только для майнинга 1080 и 1080 Ti.
- Pill cmd line params — можно указать ревизию карт для которых для запуска таблетки.
- Задержка перед стартом таблетки в секундах — задержка применения таблетки от времени запуска видеокарты.
Популярные пресеты
В этом разделе, можно выбрать пресет или шаблона разгона который используют другие пользователи Hive OS для таких же карт как у вас.

Popular Presets
Нажимаете на нужный пересет разгона и он применится к вашей карте.
Разгон нескольких карт из рига

Разгон нескольких карт из рига
Заходите в настройки разгона всех карт, и по отдельности указываете значения разгона для каждой отдельной карты. Порядок от GPU 0 до GPU N…
Разгон видеокарт от AMD
Для карт от AMD есть гораздо больше настроек для разгона, вы можете указывать не только лимит потребления, но и вольтаж на память, на чип и другие, в зависимости от поколения графического чипа.

Разгон RX 5700 XT в Hive OS
- В поле Core Clock offset, Mhz — указываем частоту в Mhz которую вы добавляете или снижаете от базовой.
- В поле Core voltage, mV — указываем значения потребления графического чипа в милливольтах.
- В поле Memory Clock offset, Mhz — указываем значение частоты видео памяти. Частота видео памяти указывается умноженная на 2. Т.е. если вам нужно увеличить частоту на 1000 MHz, вбиваете 2000 Mhz. Как и для карт NVIDIA.
- В поле Memory voltage, mV — указываем значения потребления видеопамяти в милливольтах.
- В поле Power Limit — указываете предел потребления карты в ваттах.
Polular presets — работают так же как и на картах Nvidia. Выбираете нужный шаблон и применяете его.
Разгон AMD GPU
Топ 10. лучшие программы для майнинга 2021
Прежде чем изменять какие-либо настройки, вы можете запустить команду , чтобы узнать текущие настройки графического процессора. Чтобы сделать это удаленно со своей панели, перейдите к своему работнику и нажмите кнопку «Запустить команду» на панели инструментов в верхней части экрана.
Вы можете указать одно значение для всех карт или список значений для каждой карты, разделенный пробелом. Например: 150 — одно значение для всех графических процессоров. 0 100 0 0 0 140 — означает GPU0 = нет, GPU1 = 100 и т.д.

Окно AMD OC
Поле Algo используется для указания настроек разгона для определенного алгоритма. Вы можете создать отдельный набор параметров разгона для каждого алгоритма отдельно или выбрать настройку по умолчанию, которая будет применяться ко всем алгоритмам, но может быть перезаписана самими настройками алгоритма.
- Core Clock (Mhz) — устанавливает частоту ядра. Хорошее значение будет около 1100. Если состояние ядра отключено, то для установки частоты будет использоваться состояние по умолчанию 5. Все значения должны быть абсолютными.
- Core State (Index) — это необходимо, если вы попытаетесь понизить питание видеокарты. Вы должны использовать этот параметр совместно с настройками Core Clock и Core Voltage. Это называется DPM (Dynamic Power Management) или «Уровень мощности» ядра GPU. Для RX-графических процессоров это значение от 1 до 7. Значение по умолчанию — 5. Уменьшите значение до нисходящего потока. Если вы решите установить одно из состояний по умолчанию, вам не нужно устанавливать какие-либо значения в Core Clock и Core Voltage.
- Напряжение ядра (мВ) — необходимо, если вы попытаетесь понизить напряжение ядра видеокарты. И вы должны установить Состояние ядра или по-умолчанию 5 состояние будет использоваться для установки напряжения. Вы можете установить значения, такие как 900, значение mV или значения, такие как 65284 из таблицы VBIOS.
- Memory Clock (Mhz) — устанавливает тактовую частоту памяти. Все значения являются абсолютными.
- Mem State (Index) — очень продвинутый параметр. Измените это, если есть проблемы с undervolting. Если все работает в пределах спецификации — не меняйте это значение. Известно, что RX-карты имеют 1 или 2 состояния памяти (3 в том числе 0 — незанятое состояние). По умолчанию будет выбрано самое высокое состояние. Но некоторые редкие карты, как известно, не поддаются восстановлению в самом высоком состоянии и должны выбрать нижний. Например, самое высокое значение равно 2, и для undervolting вам нужно установить состояние в 1. Вы должны использовать этот параметр с настройкой Memory Clock.
- Вентилятор (%) — для установки скорости вращения вентилятора. Имейте в виду, что майнеры, подобные claymore, все еще будут контролировать скорость вращения вентилятора. Вы должны отключить управление вентилятором в конфигурации майнера, чтобы это работало. Советуем оставить это поле пустым, если вы включили AutoFan. Мы напишем больше о AutoFan в наших будущих статьях.
- Aggressive undervolting — выбирает заданный разогнанный параметр для каждого состояния DPM.
Нажмите «Сохранить», и все готово.
Как включить уведомления в Hive OS на Telegram или Discord
Вы можете настроить уведомления по различным событиям в системе и получать их на свой telegram или discord. Какие уведомления можно получать на Telegram и Discord с Hive OS:
- Воркер в сети
- Воркер не в сети
- Воркер загрузился
- Сообщения об ошибках
- Предупреждающие сообщения
- Информационные сообщения
- Выполненные без ошибок
- GPU Temp >= Red Temp + 3°
- Почасовой отчет
- Скорость вентилятора >= Порог + 5%
- Коэф. подтв. шар >= Порог — 5%
- Средняя нагрузка (15 мин) >= Порог + 1
- Потеря GPU/платы
- GPU MEM TEMP >= Red MEM TEMP + 3°
- CPU TEMP >= Red CPU TEMP + 3°
- ASIC Board TEMP >= Red ASIC TEMP + 3°
Список уведомлений очень большой. Что в целом позволит вам во время узнавать и реагировать на любые события на ферме.
Как настроить эти уведомления?
Переходите на Фермы и выбираете нужный Воркер, там ищем вкладку — Настройки. Спускаемся к Уведомлениям.

Уведомления на telegram или discord в hive os
Для настройки уведомлений, перейдите по ссылке на Hive OS Bot, получите код в боте и на email. Введите их в системе и подписка будет оформлена.

Уведомления в Telegram в Hive OS
Что такое HiveOS и почему она подходит для майнинга

Hive OS
(Хайв ОС)
— это разработанная специально для использования в майнинге криптовалют операционная система из семейства Linux (на базе Ubuntu). В ней собрано множество программных решений, значительно упрощающих процесс настройки и контроля добычи криптовалют на популярных GPU-устройствах (фермах и ASIC-майнерах).
Благодаря HiveOS, исчезает необходимость поочередного подключения видеокарт (кто майнит на Windows, знают, о чем речь), скачивания, установки и обновления разнопланового майнингового ПО и драйверов, а также редактирования множества bat-файлов.
Эта система поддерживает работу с графическими ускорителями Nvidia и AMD, не требовательна к ресурсам используемого «железа» (хватит 2 Gb ОЗУ) и может стабильно работать даже со старыми сокетами AM2/774. При этом в одном риге может быть установлено до 19 видеокарт включительно.
Причем контроль может быть как глобальным, то есть сразу над несколькими ригами, так и точечным — над отдельными фермами или видеокартами.

Перечень задач, которые можно выполнять таким образом на Хайв ОС, просто впечатляет:
Все это очень удобно, особенно когда нет возможности физически находиться рядом с оборудованием, чтобы решить возникнувшие в процессе майнинга проблемы.
Правда, плата эта довольно символическая, если учесть перечень возможностей, которые в итоге получает пользователь.
Обновление системы Hive OS и обновление драйверов для видеокарт
Какая версия Hive OS установлена?
Для обновление Hive OS, обратите внимание, не Ubuntu на базе которой написана Hive OS, а именно Hive OS, необходимо зайти в ваш воркер.

Обновление Hive OS
Желтым цветом вы увидите последнюю версию системы, а рядом белым цветом будет обозначена текущая версия Hive OS. В моем случае, стоит 0.6[email protected], а последняя версия на данный момент [email protected].
Обновление Hive OS до последней версии (Upgrade)
Для обновления Hive OS до последней версии, нажмите на желтую иконку («Upgrade or Downgrade»).

Обновление Hive OS
Во всплывающем окне, вы можете выбрать версию на которую вы можете обновиться, а также почитать основные изменения в новой версии. Выбрав версию, нажимаете серую кнопку внизу «Upgrade». После нажатия кнопки, нужно будет дождаться процесса обновления. Обычно это занимает не более 2х минут.

Процесс обновления
Кнопка Reboot after complete — обновит воркер после успешного обновления Hive OS.
Как откатиться на предыдущие версии Hive OS (Downgrade)
В той же иконке (Upgrade or Downgrade), выбираем предыдущие версии на которые мы можем сделать откат.

Белым цветом написаны предыдущие версии системы на которые вы можете откатится. Выбираете нужную и нажимаете Upgrade. Все очень просто.
Как обновить драйвера для карт NVIDIA
Обновление драйверов в Hive OS можно сделать только для карт Nvidia, для карт AMD драйвера обновляются вместе с дистрибутивом сомой системы. Т.е. при обновлении версии Hive OS. Прежде чем обновлять драйвера, посмотрите какие драйвера установлены на вашем риге.
Для этого перейдите в Фермы — Воркеры — Выберите нужный воркер и нажмите на него. Попав в воркер, можно посмотреть версию драйверов.

Версия драйвера в HiveOS
В нашем случае версия драйверов — 455.45.01.
Следующий шаг, это узнать последнюю актуальную версия драйвера для карт Nvidia. Нужно запустить Shell.
Находясь в воркере, выбираем «Удаленный доступ» и «Hive Shell Start».

Hive Shell старт
После запуска Hive Shell, открываем окно Hive Shell.

nvidia-driver-update —list
Вводим команду nvidia-driver-update —list.
Вы увидите список доступных драйверов для установки. Узнаете версию Cuda для вашего устройства.
Для обновления драйвера введите команду upt update.

upt update
После выполнения этой команды, вводим команду на обновление драйвера.
Если есть более новая версия драйвера, вводите команду nvidia-driver-update 455.38 (указываете версию драйвера), либо просто вбиваете команду nvidia-driver-update и он будет ставить самую последнюю актуальную версию.

nvidia-driver-update
Обновления займет пару минут, после успешного обновления драйверов на hive os для nvidia, вы должны увидеть следующее окно:

Nvidia settings reinstall seccessful
Все, обновление драйвера прошло успешно.

Driver installation successful
Как обновить драйвера для карт AMD в Hive OS
Драйвера для карт AMD обновляются вместе с обновлением образа Hive OS. Других варианты не рекомендуются.
Управление работой рига
Тут же, на панели администрирования выбранного рига можно перезапустить, остановить, запросить лог или конфиг активной программы-майнера, просмотреть информацию об используемом кошельке.

Log — представляет собой снимок рабочего экрана майнера. При нажатии на ссылку «Log» отправляется команда на сервер Hive OS, а с него на ваш риг, после чего с рига возвращаются на сервер и к вам в веб-интерфейс запрошенные данные.

Config — отобразит настройки программы майнера, которые мы вводили в кошельке.

Для полного выключения или перезагрузки фермы необходимо воспользоваться кнопками «Reboot» и «Shutdown» рядом с которыми отображается системная информация и технические характеристики компьютера, на котором запущена система (Статус online-offline, статус майнера, время работы, название материнской платы и Ip adress).
Linux Shell Execute — предназначена для ввода Shell команд. По умолчанию в системе имеются несколько команд по запросу информации о работе видеокарт.

Зомби режим в Hive OS
Шаг 1: Заходим в Flight Sheets (полетные листы) и создаем полетный лист. Монету выбираем ETH, прописываем свой кошелек (нужно предварительно его создать), пул, и майнер. Выбираем TeamRedMiner и нажимаем Настроить ( Setup Miner Config).

Создаем Flight Sheets (полетный лист) и выбираем майнер TeamRedMiner
В насройках майнера, находим поле Extra config arguments и вводим следующую команду — —eth_4g_max_alloc 4076.

—eth_4g_max_alloc 4076
Эта команда указывает сколько видеопамяти в карте будет использоваться под DAG файл. Все что больше этого значения будет размещаться в оперативной памяти. Чем выше эта цифра, тем меньше будет падение хэшрейта в майнинге. У нас стоит 4076 mb. Это цифру вам нужно подобрать самим. Если на 4076 все работает стабильно, попробуйте поднять на 10 mb.
Нажимаем Apply Changes и сохраняем полетный лист. Полетный лист называем как то понятно, Zomby List или как то так.
Более подробнее про майнинг на картах с 4GB видеопамяти читайте в статье по майнингу на RX 480, RX 570, RX 580.
Проверка логов в Hive OS для поиска проблем и ошибок
В Hive OS есть несколько журналов с логами, которые вы можете анализировать для поиска проблем, ошибок или проверки работы. Вы можете посмотреть журнал майнера и журнал системы.
Как посмотреть лог майнера в Hive OS

Miner Log
Ищем иконку под названием «Miner Actions» и выбираем раздел Miner Log. Вы увидите следующий лог из последних 100 строк работы майнера (это даже не лог, а просто экран майнера):

Miner Log
Настоящие файлы хранятся в /var/log/miner/xxxx/*.log. Как их увидеть?
Открываем «Remote Access» и выбираем Hive Shell Start.

После загрузки терминала, вы увидите иконку открытия терминала в новом окне:
Нажимаем на нее и переходим в терминал, который откроется в соседней вкладке.

У нас откроется терминал в котором мы прописываем команду «mc» и нажимаем Enter.
Переходим стрелками в папку /var/log/miner/xxxx/*.log. Где xxx — это название вашего майнера и внутри этой папки смотрим папку с логом. Для просмотра лога нажимаем F3. Для выхода из mc нажимаем F10.
Как посмотреть системный лог в Hive OS
Для доступа в главный системный журнал, вбейте в Hive Shell — less /var/log/syslog
Подключение при помощи Shellinabox, VNC
Для получения доступа к ригу имеются такие инструменты как Shellinabox и VNC. Они будут работать в случае нахождения компьютера с которого производится подключение в одной сети с фермой. Первый инструмент не имеет графического интерфейса, и все команды нужно будет вводить вручную. Второй инструмент чем то похож на TeamViewer и предоставляет графический интерфейс.
Для подключения потребуются логин: user
и пароль:
1
.
Думаю, на этом пора закончить эту статью о запуске и настройке Hive OS
. Надеюсь у вас все получилось как и у меня. В скором времени появятся подробные обзоры всех функций данной операционной системы. Happy mining!
Target core temp hive os что это
—algo или краткий синоним этой команды -a — выбирает алгоритм майнинга.
Важно! Используйте либо длинный синоним, —algo= либо короткий -a . Вам не нужно использовать вместе два варианта одной и той же команды.
Дальнейшие команды будут разделены запятыми. Сначала короткий синоним, а затем длинный. Не забудьте использовать только один вариант.
Доступные на данный момент алгоритмы:
teamredminer.exe -a ethash
URL пула
-o — устанавливает URL пула и ПОРТ пула. В настоящее время поддерживаются протоколы stratum+tcp и stratum+ssl URL-адреса.
В этом примере URL-адрес ethash.poolbinance.com и порт 8888 . Значения должны быть разделены знаком :
Каждый раз, когда указывается эта опция, будет запускаться новая конфигурация пула.
Параметры для каждого пула (например -u , -p ) необходимо будет снова явно указывать для каждого нового пула. (См. пример файла start_multipool.sh/bat ).
Стратегия нескольких пулов для майнера устанавливается с —pool_strategy опцией.
SSL/TLS (для продвинутых пользователей)
Также имеется специальная поддержка расширенных настроек SSL/TLS, когда вам нужно передать имя хоста SNI конечной точке SSL. Например, это необходимо для конечных точек SSL, которые действуют как интерфейсы для нескольких хостов и должны знать, для какого из них предоставить сертификат. В таких случаях используйте следующий формат:
Это подключится к pool.tunnel.com:3333 , но передаст pool.realhostname.com в качестве имени хоста SNI на этапе подтверждения SSL. Разумеется, два имени хоста также могут быть идентичными.
Имя пользователя (логин пула) или адрес кошелька
-u , —user=USERNAME — устанавливает имя пользователя или адрес кошелька для авторизации майнинг-пула.
Если на пуле нет регистрации, то вместо логина нужно указать адрес кошелька.
Пароль (необязательно)
-p, —pass=PASSWORD — устанавливает пароль для авторизации пула.
Имя воркера (worker name)
Воркер — это название вашего виртуального “рабочего”. Это название указывается для простоты отслеживания статистики.
.worker — установите простое имя воркера для отслеживания вашего рига (фермы) в пуле. Имя работника указывается после знака wallet_address и перед ним ставится точка.
Минимальная настройка для запуска должна обеспечить только:
- адрес пула,
- адрес кошелька и
- имя воркера.
Просто скопируйте и измените адрес кошелька на адрес вашего кошелька. Это пример для Ethermine:
teamredminer.exe -a ethash -o stratum+tcp://eu1.ethermine.org:4444 -u 0x360d6f9efea21c82d341504366fd1c2eeea8fa9d.worker_name -p x
Список аргументов командной строки
-h , —help Display help message and exit.
—debug Enables debug log output.
—disable_colors Disables console output colors.
—force_colors Forces console color output even if the terminal does not seem to support them.
—api_listen=IP:PORT Enables the sgminer compatible api. IP:PORT is optional. If present, the IP:PORT combo decides the interface(s) and port to listen to. Default is 127.0.0.1:4028 . For external access, use e.g. 0.0.0.0:4028 . It’s also valid to only specify the port, e.g. 4029 .
—cm_api_listen=IP:PORT Enables the claymore compatible api. IP:PORT is optional. If present, the IP:PORT combo decides the interface(s) and port to listen to. Default is 127.0.0.1:3333 . For external access, use e.g. 0.0.0.0:3333 . It’s also valid to only specify the port, e.g. 3334 .
—cm_api_password=PSW Sets the required password for the CM compatible api interface.
Журнал (Logs)
—log_file(=FILENAME) Enables logging of miner output into the file specified by FILENAME . If no filename is provided, the miner will log to trm_<algo>_<yyyymmdd_hhmmss> .log in the current working directory. If the log file already exists, the miner will append.
-l, —log_interval=SEC Set the time interval in seconds for averaging and printing GPU hashrates. SEC sets the interval in seconds, and must be > 0.
—log_rotate=SZ[,CNT] Enables log rotation. The SZ value sets the log size after which a new log file will be created. The SZ value supports the suffixes ‘k’, ‘M’, and ‘G’ and will multiply the value by 1024 , 1048576 , and 1073741824 respectively.
The optional CNT value sets the maximum number of old log files to keep. For example the option —log_rotate=4M,16 will cause the miner to switch to a new log file once the current log file exceeds 4194304 bytes in size, and the miner will keep the last 16 such files and delete older ones.
—short_stats Disables the full gpu state output in each hashrate output, like it was before 0.7.10.
—long_timestamps Enables microsec timestamps in the logs instead of seconds only.
—high_score Enables printouts of the top 15 shares found since miner start in the stats output.
—pool_debug Logs all pool traffic.
Комиссия (DevFee)
—dev_location=LOC Selects a specific location for the dev fee connection. Only use this if you see continuous dev fee connection issues reported by the miner. The connection management normally works well in all locations.
Available options are:
- world — Anywhere in the world except for mainland China.
- cn — Mainland China.
- non-gcp — Countries with blocked access to Google Services (e.g. Iran, Cuba).
Производительность
—enable_compute (Windows only) Enables compute mode and disables crossfire on necessary gpus.
—restart_gpus (Windows only) Restarts all configured gpus before mining, i.e. disable+enable PCI device.
—uac (Windows only) Enable privilege escalation when the miner runs tasks like restarting gpus.
You can always avoid this by running the miner directly as Administrator. This will trigger the standard Windows escalation prompt, so you have to be available to click ‘Yes’.
If this is not enabled, tasks that require Administrator privileges will fail when the miner is running under a basic user account.
Note: this might not be enabled for all algos.
—allow_dup_bus_ids Allows multiple gpus using the same pci bus id. This should only be used for Radeon Pro Duo cards and similar hardware, it’s normally an indication of a broken OpenCL environment.
Подключение к пулу
-o, —url=URL Sets the pool URL. Currently stratum+tcp and stratum+ssl URLs are supported.
- Each additional time this option is specified will start a new pool config.
- Per-pool options (such as -u, -p) will need to be explicitly specified again for each new pool. (See the example start_multipool.sh/bat file)
- The multi-pool strategy for the miner is set with the –pool_strategy option.
There is also special support for advanced SSL/TLS setups where you need to pass a SNI hostname to the SSL endpoint. For example, this is necessary for SSL endpoints that act as frontends for multiple hosts and need to know which one to provide a certificate for. In such cases, use the following format:
This will connect to pool.tunnel.com:3333 but pass pool.realhostname.com as the SNI hostname in the SSL handshake phase. The two hostnames can of course be identical as well.
-u , —user=USERNAME Sets the username for pool authorization.
-p , —pass=PASSWORD Sets the password for pool authorization.
—pool_force_ensub Forces an extranonce subscribe request for supported pools unknown to the miner.
—pool_no_ensub Prevent miner from sending extranonce subscribe request to the pool.
—pool_broken_rpc Tells the miner to only allow a single outstanding rpc request on the pool connection. This is a work-around for pools that violate the json rpc specification regarding rpc IDs.
—pool_ratio=RATIO Sets the hashrate ratio between pools when using multiple pools with the the load_balance or quota pool strategies (see —pool_strategy ). By default all pools use the ratio value 1. For example, using this option with a value of 2 on just one pool will make that pool receive twice the hashrate as the other pools since their ratio will still be the default value of 1.
Глобальные опции пула
—pool_connect_TO=SEC Set the time-out for attempting to connect to a pool. SEC is the time to wait in seconds. Default is 10.
—pool_rpc_TO=SEC Set how long the miner will wait for an unanswered RPC to the pool. After this time, the miner will reconnect to the pool. SEC is the time to wait in seconds.
Default is 60.
—pool_max_rejects=N If a pool rejects N shares in a row, the pool connection is reset. This is to prevent against pools that invalidates mining sessions without disconnecting the user.
Default value is 5.
—pool_share_limit_ms=N If a pool takes longer than N ms to accept or reject a share, kill the current connection and reconnect. This is intended for pools that often get issues with some of their servers, but reconnecting means being load-balanced to a different and hopefully better server. Default value is no timeout.
—pool_strategy=STRAT Sets the strategy for selecting pools when running with multiple pools.
The available values are:
- priority,
- load_balance,
- quota, and
- min_epoch.
The default is priority.
- priority : The miner will use pools in the order they are listed, only moving on to the next pool if the previous cannot establish a connection.
- load_balance : The miner will evenly balance the hashrate across all currentlyconnected pools. The ratio of hashrate between pools can be set with —pool_ratio .
- quota : The miner will evenly balance the total hashes completed across all pools. If a pool disconnects and later reconnects, the miner will move hashrate to the pool until the total hashes for each pool is balanced.
The ratio of hashrate between pools can be set with —pool_ratio .
- min_epoch : ETH + ZIL switching strategy. The miner will always mine the lowest epoch among all connected pools, and in case of a tie, the first connected pool.
Therefore, specify your ETH mining pool as the first/primary pool, then the ZIL pool as the second pool. You can also use ‘eth_zil’ as the name for this strategy.
—no_ntime_roll Prevents the miner from rolling ntime in the block header, only using the value provided by the pool. This needs to be enabled for some pools when mining x16rt .
—no_stale_submit Prevents the miner from submitting shares that are not for the most current pool job.
Опция выбора видеокарт
—platform=INDEX Sets the index of the OpenCL platform to use. If not specified, platform will be auto-detected. Linux with multiple platforms is only supported using no —platform arg but instead adding —bus_reorder .
-d , —devices=DEVLIST Sets gpu devices to use from detected list. DEVLIST should be a comma-separated list of device indices, e.g. -d 0,1,2,4. If not specified, alldevices on the platform(s) will be used. NOTE: by default the devices are orderedby pcie bus ordering. Use —list_devices to show indices.
—init_style=1/2/3 Specified the init style (1 is default):
- One gpu at the time, complete all before mining.
- Three gpus at the time, complete all before mining.
- All gpus in parallel, start mining immediately.
—pcie_fmt=FORMAT Sets print format for pcie bus numbers. The accepted values for FORMAT are either hex or dec . The default is dec for windows and hex for linux.
—bus_reorder Reorders the detected or specified devices after their pcie bus id. If noplatform is specified, devices will be collected from all detected AMD OpenCLplatforms. Note: As of version v0.7.0 this is the default behavior.
—opencl_order Orders the detected or specified devices in the order OpenCL presents them.
—list_devices Lists the available devices for the detected or specified platform and exits immediately. Bus reordering will be implemented in the displayed order.
—nr_cu_override=X,Y. Overrides the nr compute units per gpu as presented by the OpenCL API. This is primarily useful for Vega 64s flashed with 56 biosed and where the driver is reporting 56 CU instead of the true count. Provide a comma-separated list of the override CU count per gpu as value for the argument.
You can skip gpus and do not need to provide values for all gpus in the rig. Example for a mixed rig of two Vegas at index 1 and 3 and two other gpus: –nr_cu_override=,64,,64. You can verify your argument by also adding —list_devices before mining.
Варианты управления разгоном / напряжением (только для Windows, BETA функциональность)
The miner has basic functionality for setting core and mem clks and their respective voltage, as well as selecting between the win driver’s built-in timings. For each available argument below, you enumerate values for gpu(s) in the rig in a comma-separated list.
Some arguments are not used for certain gpus. You can skip gpus in the list.
The miner always sets and uses the highest p-state for both core and mem for GCN gpus (Polaris, Vega). Please note that Rx Vega gpus must have a powerplay table modification of the mem p2 state before being able to run a voltage lower than 900mV. Moreover, Big Navi gpus also still need to use e.g. MorePowerTool to make powerplay table modifications, for example for enabling setting a lower voltage. The miner might add support for powerplay table-related functionality in the future.
—clk_debug Enable start-up log printouts related to setting clocks/voltages/timings.
—clk_core_mhz=MHZ1,MHZ2. Sets the core clk per gpu in MHz.
—clk_core_mv=MV1,MV2. Sets the core voltage per gpu in mV.
—clk_mem_mhz=MHZ1,MHZ2. Sets the mem clk per gpu in MHz.
—clk_mem_mv=MV1,MV2. Sets the mem voltage per gpu in mV. Not used for Navi or Big Navi gpus.
—clk_timing=V1,V2. Selects between the driver’s available mem timing sets. Not available on all gpus and drivers.
Example of a partial command line for a four gpu system where with a Rx Vega 64, 580, 5700XT and 6800 mining ethash or similar. We only specify mem voltage for the Vega and 580, and only select a driver timing value for the Big Navi:
teamredminer.exe . —clk_core_mhz=1100,1000,1275,1000 —clk_core_mv=875,850,725,675 —clk_mem_mhz=1107,2100,1820,2130 —clk_mem_mv=875,850,, —clk_timing=. 1
Варианты управления вентилятором
—fan_control(=CFG1,CFG2. ) This argument enables gpu fan control by the miner. TRM supports auto-adjusting the gpu fan speed(s) based on core, junction and/or mem temp.
We also support setting a static fan speed in percent.
Each gpu type has a fan configuration that will be used by default. We support both overriding the default configuration per gpu type as well as setting a specific config per gpu in the rig.
A fan config consists of (max) six values, separate by the ‘:’ (colon) char. The values are: core target temp, junction target temp, mem target temp, initial fan speed in percent, min fan speed in percent, max fan speed in percent. Any value can be left empty.
These are a few examples:
- ::70:50:25 Target mem temp to 70C, start fan at 50% speed, min fan speed 25%.
- 55. 20:80 Target core temp to 55C, start fan at default configuration’s speed, always keep fan between 20% and 80%.
- 55::75:80 Adjust fan so that core temp is <= 55C and mem temp is <= 75C, start fan at 80%.
- . 100 Set static fan speed to 100%, never adjust based on temps.
The fan configuration used for a gpu is derived in the following precedence order:
- The —fan_control argument was passed a list of configurations and included an entry for gpu X.
- The default fan configuration for this gpu type was overridden with a —fan_default_<type>=. parameter.
- Use the built-in default fan configuration for this gpu type.
In the list above, if the chosen configuration is missing the start value for the fan the setting from the next configuration is used.
NOTE: fan support is a beta feature and will not work better than the support the drivers provide. For example, many times the drivers under linux don’t allow forcing a fan to 100% using the sysfs pwm support.
—fan_default_polaris=CFG Set the default config used for all Polaris gpus (450/460/550/560/470/480/570/580/590).
The built-in default is 55. 50 for 55C core temp and fan starting at 50%.
Note: this setting is also reused for Tonga gpus.
—fan_default_vega=CFG Set the default config used for all Vega gpus (Vega 56/Vega 64).
The built-in default is 55::70:50 for 55C core temp, 70C mem temp and fan at 50%.
—fan_default_vega2=CFG Set the default config used for all Radeon VII gpus.
The built-in default is 70::75:80 for 70C core temp, 75C mem temp and fan at 80%.
—fan_default_navi=CFG Set the default config used for all Navi (Navi10).
The built-in default is 60::80:70 for 60C core temp, 80C mem temp and fan at 70%.
—fan_default_big_navi=CFG Set the default config used for all Big Navi (Navi21).
The built-in default is 50. 70 for 50C core temp and fan at 70%. The reason for not including mem temp is a missing sensor in the Windows ADL library.
—fan_debug Enable log printouts related to adjustments.
Параметры сторожевого таймера
—no_gpu_monitor Disables the ADL (Windows) or sysfs (Linux) GPU monitor for temperature and fan speed.
—temp_limit=TEMP Sets the core temperature at which the miner will stop GPUs that are too hot.
Default is 85C. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the listis used.
—temp_resume=TEMP Sets the core temperature below which the miner will resume GPUs that were previously stopped due to the core temperature exceeding limit.
Default is 60C. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the list is used.
—mem_temp_limit=TEMP Sets the mem temperature at which the miner will stop GPUs that are too hot.
Default is not enabled. Only used if the gpu provides a mem temperature sensor.
Gpu-specific values can be provided using a comma-separated list, one value per gpu.
If a gpu doesn’t have a defined value, the first value in the list is used.
—mem_temp_resume=TEMP Sets the mem temperature below which the miner will resume GPUs that were previously stopped due to mem temperature exceeding limit.
Default is not enabled. Only used if the gpu provides a mem temperature sensor. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the list is used.
—watchdog_script(=X) Configures the gpu watchdog to shut down the miner and run the specified platform and exits immediately. The default script is watchdog.bat/watchdog.sh in the current directory, but a different script can be provided as an optional argument, potentially with a absolute or relative path as well.
—watchdog_test Tests the configured watchdog script by triggering the same action as a dead gpu after
20 secs of mining.
—watchdog_disabled Forces the watchdog to not execute. Can be used to disable the watchdog in mining os that always run with the watchdog enabled.
Ethash опции
—eth_config=CONFIG Manual ethash configuration for the miner. CONFIG must be in the form [X][M][L] .
- The [M] value selects the mode which can be ‘A’,’B’, or ‘C’.
- The B mode uses additional memory and will only work on 8+GB cards.
- The C mode uses additional memory and will only work on 16+GB cards, such as the VII, with a correctly configured system. See the ETHASH_TUNING_GUIDE.txt for more details.
- The [L] value selects the intensity and it’s range will depend on the GPU architecture.
- The [X] prefix is optional and is Navi/Big Navi only, it enables more mem operations and leads to a lower tuning [L] value. It can be beneficial whenever the auto-tuner repeatedly hits a value close to the max possible tuning value for the gpu.
Both values are optional, but if [L] is specified, [M] must also be specified.
- —eth_config=A
- —eth_config=B750
- —eth_config=XB
CONFIG can also be a comma separated list of config values where each is applied to each GPU.
Any gpu that does not have a specific config in the list will use the first config in the list.
—eth_variant_mode=X This argument controls activation of the ethash changes for ETC from epoch 390 as described in ecip-1099.
The following modes are available:
pool — Default mode. Only activates if the pool sends an algo flag containing etchash.
Once this flag is seen, all pool jobs will be assumed to be etchash unless another.
algo flag containing ethash is received.
etchash — Etchash mode. Epoch >= 390 will be assumed to be etchash, lower epochs ethash. Pool algo flags are not used.
deduce — Ignore pool algo flags and only apply a heuristics based on the current system time and known heights and times for ETC and ETH. This mode should work as a generic approach when ETH reaches epoch 390 in Jan 2021. The system clock needs to be correct.
It should also handle any profit switching setups that switch freely between ethash and etchash jobs by proxying underlying pools.
auto — As long as the pool hasn’t passed an algo flag, use deduce mode. When an algo flag is seen, switch to pool mode.
ethash — Forced ethash mode. Never apply ecip-1099.
force_etc — Forced etchash mode. Always apply ecip-1099 rules. Use for ETC testnet mining.
—eth_aggr_mode Enables automatic use of the ‘B’ mode for all Polaris 8GB cards, unless they have a different config provided by the —eth_config argument. This is the same thing as manually setting all Polaris 8GB gpus in the rig to ‘B’ mode using —eth_config .
For most gpus, this adds 0.1-0.2 MH/s of hashrate.
NOTE: 20-25% of rigs becomes less stable in this mode which is the reason it isn’t the default mode. If you experience dead gpus, you should remove this argument and run the gpus in the ‘A’ mode.
—eth_stratum_mode=MODE Sets a fixed stratum mode for ethash pools.
By default the miner will attempt to automatically determine the type of stratum the pool supports and use that mode. This automatic detection can be overriden by specifying this option. The MODE can be set to one of the following options: stratum, nicehash, ethproxy.
—eth_worker Set the worker id that will be sent to pool. This only applies to pools with ethproxy stratum mode.
—eth_hash_report=X Controls hashrate reports to the configure pools. This value is applied for all pools.
- default — let the miner decide based on stratum protocol used for each pool.
- force — always send hashrate reports, even if the pool rejects them.
- on — send a first hashrate report, disable for any pool that rejects the message.
- off — never send hashrate reports.
—eth_epoch Tests a specific ethash epoch. NOTE: you still need to provide a pool as if you were mining, but no shares will be submitted. Simulated mining only.
—eth_alloc_epoch=N Allocates enough memory for the given epoch from the start. The miner will try to allocate more if it needs to later during mining. It’s recommended for rigs with one or more 4GB cards to test and set this to the max possible value to avoid reallocations at epoch switches. Optimal Linux rigs should be able to handle epoch 380, Windows rigs a little less (373-374).
—eth_dag_buf=X,Y. The miner can allocate a single or dual buffers for the DAG. For now, the default is DUAL buffers, which matches the behavior in all recent TRM releases. However, a single buffer is slightly better, leading to a small power save for all gpu types. Only recent drivers support single large allocations larger than 4GiB, typically from Adrenalin 20.9.1 and amdgpu-pro 20.x. The miner can automatically use single buffer mode when possible using this argument, as well a force single or dual buffers per gpu.
Supported values are
- A(uto),
- S(ingle),
- D(ual).
You can enumerate a comma-separated list for all gpus in the rig, or a single value for all gpus. A gpu that does not have a value in the comma-separated list will use the first value. Hence, to enable auto mode for all gpus, pass —eth_dag_buf=A NOTE: 4GB gpus will be forced to use dual buffers.
—eth_big_mode_adjust=X,Y. When using B- or C-modes, the miner runs better the more vram it can allocate. Unfortunately the drivers aren’t accurate reporting how much memory it’s possible to allocate, especially on Windows.
The miner will use a safe conservative number of 256MiB (Linux) and 512MiB (Windows) as an offset from the available vram size. If you want change this number, you can do so using this argument by providing.
a comma-separated list with values for one or more gpus. Values for gpus not running B/C-mode will be ignored. If a gpu doesn’t have a value in the list, the first provided value is used instead.
The allowed interval is [-64, 2048]. The higher number, the less vram is allocated on the gpu.
—eth_4g_max_alloc=X,Y. This argument allows mining on 4GB gpus after they no longer can store the full DAG in vram.
You pass either the max epoch to allocate memory for, or the raw nr of MB to allocate. You can provide a single value that applies to all 4GB gpus in the rig, or use a comma-separated list for specifying different values per gpu. Values for non-4GB gpus are ignored.
—eth_dag_slowdown=N Slows down the DAG generation. Pass a single digit 0-9. 0 means no slowdown (<= 0.7.9 behavior), 1 means minimal slowdown, 9 means max. Default value: 4 for a slight slowdown.
—eth_stagger Enables staggering of gpus when building a new DAG. This is more lean on PSUs that don’t like going from 0-100% load on all gpus at the same time.
—eth_no_stagger Disables –eth_stagger. Already the default behavior from 0.7.18. Argument kept for backwards compatibility only.
—eth_ramp_up Adds ramping up the intensity on all gpus after a DAG build, gpu disable/enable or network outage. Can help rigs with crashes right between the DAG build and starting mining.
—eth_no_ramp_up Disables —eth_ramp_up . Already the default behavior from 0.7.18. Argument kept for backwards compatibility only.
—eth_direct_abort Uses a different mechanism to abort ongoing gpu jobs. Recommended for Vegas in ROCm environments to minimize stale shares. Will apply to Vega and Polaris gpus in the rig only.
—eth_dag_alloc_patch Some motherboards with outdated bios can see hw errs typically on the first or last gpu in the system.
Use this argument to force a patched dag allocation strategy that most often solves the issue.
Upgrading your bios often solves the issue as well.
—eth_hashwatch(=M,M) Defines a min/max watchdog hashrate in MH/s expected when gpus are hashing. If a GPU falls outside of this range for too long it will be considered faulty and the watchdog will be triggered. The default min/max values are 2 MH/s and 150 MH/s.
To activate with default values, use —eth_hashwatch . To set your own values, use e.g. —eth_hashwatch=1.25,60 . The same range is used for all gpus in the rig. A negative value for one side disables it, e.g. use —eth_hashwatch=-1,1000 to handle gpu resets that result in huge fake hashrates but no minimum check.
—eth_dag_cache(=EPOCH) Enables saving eth DAGs from jobs with different epochs to prevent having to rebuild them in the future if jobs with the old epochs are received again. At most one DAG will be saved if GPU memory space allows. This is useful for switching pools such as eth+zil mining.
If you want to prebuild a certain epoch immediately at startup, add the optional value. Eth+zil switching miners should use —eth_dag_cache=0 . Only ethash (and not etchash) epochs can be prebuilt at this time.
—eth_dag_cache_resv=MEM Sets the amount of GPU memory the miner will attempt to leave unused when running with DAG caching enabled (see –eth_dag_cache). The argument MEM is the amount of memory to leave unused in mebibytes. The default value is 256.
—eth_dag_cache_verify Enable dag cache read and verification after a finished dag build. This will detect situations where the dag cache had bit errors and the resulting dag is partially broken.
We have seen this happen increasingly on Vegas as the dag has grown bigger. When detected, a new buffer will be allocated for the dag cache and the dag build restarted.
—eth_no_4gb_kernels Disable the ethash 4GB kernels and always use the regular kernels that assume the DAG will always fit in available vram on all gpus.
This is useful when mining ETC or ethash coins at lower epochs than ETH since the regular kernels have a better performance profile.
—eth_micro_delay=VAL Navi gpus only: adds a delay (measured in microseconds) when reenqueueing work on the gpu(s).
Weaker PSUs driving many gpus can sometimes not handle the “slew rate” when multiple gpus happen to reenqueue work at exactly the same time. Setting this to e.g. 32 will smoothen out the transition from no load to 100% load enough to lower the slew rate on such rigs.
The typical indication of this issue is hard hangs where the rig becomes unresponsive requiring a power cycle to reboot, but it can also be regular gpu crashes. Valid values are 1-128. Not using this argument means no delay, value zero.
Progpow опции (kawpow, firopow)
—prog_config=CONFIG Manual progpow configuration for the miner. CONFIG must be in the form [M][L].
- The [M] value selects the mode which can be either ‘A’ or ‘B’.
- The ‘B’ mode typically results in better performance but is only available for
- Vega on linux and Navi (linux or windows).
- The [L] value selects the intensity and it’s range will depend on the GPU architecture.
Both values are optional, but if [L] is specified, [M] must also be specified.
- —prog_config=A
- —prog_config=B750
CONFIG can also be a comma separated list of config values where each is applied to each GPU. For example: —prog_config=A,B750,,A288
Any gpu that does not have a specific config in the list will use the first.
—prog_height=VALUE Sets a fixed block height for progpow algorithms for benchmarking purposes.
Note that using this option needs a pool connection but will not submit shares.
—prog_strict Forces miner to always generate strictly accurate kernels. By default the miner will generate relaxed kernels that use less computation power but can result in occasional invalid shares.
—prog_dag_slowdown=N Slows down the DAG generation. Pass a single digit 0-9. 0 means no slowdown (<= 0.7.9 behavior), 1 means minimal slowdown, 9 means max. Default value: 4 for a slight slowdown.
—prog_stagger See `–eth_stagger.
—prog_ramp_up See `–eth_ramp_up.
—prog_no_stagger See `–eth_no_stagger.
—prog_no_ramp_up See `–eth_no_ramp_up.
—prog_micro_tune=X,Y. This option enables a small retuning session for every new random code block. This is important for Polaris gpus to run at their max speed. For Vegas and Navis it usually does not improve performance. The default AUTO mode enables it for all Polaris gpus but disables it otherwise.
The only reason to disable it would be for stability purposes. The argument value is a comma-separated list of values, one per gpu. If a gpu is missing a value, the value for the first gpu is used. Please note that setting a manual prog_config will effectively disable the micro-tuner as well. Available values are:
-
- turn OFF progpow micro-tuning for this gpu.
-
- turn ON progpow micro-tuning for this gpu.
-
- let the miner decide if micro-tuning should be enabled (AUTO).
Cryptonight опции
—rig_id Set the rig identifier that will be sent to the pool. This is only used for cryptonight pools.
—cn_config=CONFIG Manual cryptonight configuration for the miner. CONFIG must be in the form [P][I0][M][I1][:xyz], where [P] is an optional prefix and [:xyz] is an optional suffix.
For [P], only the value of ‘L’ is supported for low-end GPUs like Lexa/Baffin. [I0] and [I1] are the thread intensity values normally ranging from 1 to 16, but larger values are possible for 16GB gpus.
[M] is the mode which can be either ‘.’, -‘, ‘+’ or ‘*’. Mode ‘.’ means that the miner should choose or scan for the best mode.
Mode ‘*’ both a good default more and should be used if you mine on a Vega 56/64 with modded mem timings.
The exceptions to this rule are small pad variants (cnv8_trtl and cnv8_upx2), they should still use ‘+’. For Polaris gpus, only the ‘-‘ and ‘+’ modes are available.
NOTE: in TRM 0.5.0 auto-tuning functionality was added, making manual configuration of the CN config modes unnecessary except for rare corner cases. For more info, see the tuning docs and how-to documents bundled with the release.
- —cn_config=15*15:AAA
- —cn_config=14-14
- —cn_config=L4+3
CONFIG can also be a comma separated list of config values where each is applied to each GPU.
Any gpu that does not have a specific config in the list will use the first config in the list.
—no_cpu_check Disables cpu verification of found shares before they are submitted to the pool.
Note: only CN algos currently supports cpu verification.
—no_lean Disables the CN lean mode where ramp up threads slowly on start or restart after network issues or gpu temp throttling.
—no_interleave=DEVS Lists gpu devices where CN thread interleave logic should be not be used.
The argument is a comma-separated list of devices like for the -d option.
Use this argument if some device(s) get a worse hashrate together with a lot of interleave adjust log messages.
—alloc_patch=DEVS Lists gpu devices that loses hashrate between TRM v0.4.5 and later versions. With this argument a simpler mem allocation strategy is used, and the old (higher) hashrate should be restored. Auto-tuning mode can still be used.
—auto_tune=MODE Enable the auto-tune mode upon startup. Only available for CN variants. MODE must be either NONE, QUICK or SCAN. The QUICK mode checks a few known good configurations and completes within 1 min. The SCAN mode will check all possible combos and will run for 20-30 mins. Setting MODE to NONE disable the auto-tune feature. The default mode is QUICK.
—auto_tune_runs(=N) Executes multiple runs for the auto tune, each time decreasing the unit of pads used -1 in one of the threads (15+15 -> 15+14 -> 14+14 -> 14+13 -> …). You can specify the explicit nr of runs or let the miner choose a default value per gpu type (typically 3-4).
—auto_tune_exit If present, the miner will exit after completing the auto-tuning process. This is helpful when you want to scan for optimal settings and then use the resulting command line arg printed by the miner.
—allow_large_alloc If present, and when the driver indicates there is enough GPU vram available, the miner will be more aggressive with the initial memory allocation. In practice, this option means that Vega GPUs under Linux will start the auto-tuning process at 1615 rather than 1614 or 15*15.
MTP опции
—allow_all_devices Some algos can’t be mined on e.g. 4GB gpus. Those gpus will be disabled automatically by the miner. This argument overrides this logic and allows mining on all specified or detected devices.
X16* опции
—hash_order=VALUE Sets a fixed hash order for algorithms like x16r for benchmarking purposes.
Note that using this option needs a pool connection but will not submit shares.
The standard benchmark hash order for x16r is —hash_order=0123456789abcdef .
Nimiq опции
—nimiq_worker=VALUE Sets the worker/device name for nimiq to pass to the pool(s).
—nimiq_no_proxy Disables the automatic Nimiq proxy executed as a separate process. This means that the host and port passed to the miner must be pointing to a proxy.
—nimiq_proxy=VALUE Overrides the default path to the Nimiq proxy. The default is trm_nimiq_proxy-win.exe. and trm_nimiq_proxy-linux in the current miner director.
—nimiq_port=VALUE Overrides the default local port (4444) used for the Nimiq proxy. This can be used if your system is already using port 4444 for some other tcp/ip service.
Verthash опции
—verthash_file=FILE Sets the filename to be used to load/store the verthash data file. If this option is specified when the verthash algo is used, the miner will attempt to load the verthash data from the file. If the file does not exist, the miner will generate the verthash data and then save it in the file for future use.
If this option is not specified the miner will generate the verthash data in system memory on every start.
—verthash_max_uploads=N Some motherboards have issues with all gpus in the rig uploading the verthash table at the same time. This argument limits the number of concurrent gpus that are uploading the table at the same time at startup. Allowed values are 1-32. The default value is 4.
Autolykos2 опции
—autolykos_mem_adjust=N Sets the amount of memory in MiB that the miner should leave unused when allocating GPU buffers for autolykos. The default value is 384 on linux and 512 on windows.
For GPUs with displays attached, the default is increased by 512. If dual mining with ZIL, the default value is increased by 1024. The option can also be provided with a comma separated list of values where each value is applied to each GPU. If an empty value is specified in the list, the default will be used for that GPU. If a value is not specified for a GPU it will use the first value in the list.
—autolykos_slowdown=N Adds a slowdown of the pad build process. Valid values are 0-100. The default is 0, no slowdown.
—autolykos_ignore_diff Ignores the difficulty sent by the pool and only uses the 256-bit target provided in jobs.
Some pools don’t follow the ERGO reference miner pool implementation, in which case this argument might help. NOTE: this will be applied to all pools.
ZIL dual mining опции
—zil_start or —zil Starts the ZIL dual mining config. Between this and the —zil_end marker , all arguments are applied to the ZIL mining rather than the primary algo. It’s expected that the primary algo has been set up in earlier arguments. The intention is that you can add a —zil . —zil_end configuration to any working TRM configuration algo and things will work out of the box.
This argument automatically sets a range of default settings you want to use for ZIL:
- Cached copy of the ZIL epoch 0 DAG.
- Adjustment of memory allocated for the primary algo to fit the ZIL DAG.
- Choose ethash A-mode for the ZIL mining.
- Use the standard faster kernels for 4GB gpus since the DAG is max 1GB.
The minimal working setup is to only provide a ZIL pool that is ok with the miner ignoring the primary coin jobs and only mines during the ZIL windows. This is an example for ezil.me:
—zil -o stratum+tcp://eu.ezil.me:5555 -u <eth wallet>.<zil wallet>.<worker name> -p x —zil_end
For more info, read the ZIL dual mining guide packaged with the TRM release.
—zil_end Marks that we’re done with the ZIL mining config and all following arguments are for the primary algo. This argument isn’t strictly necessary, but should be included for mining distros since the user has no guarantee what arguments will be added automatically at the end of the command line by the distro.
—stats_mode=single/dual When adding ZIL dual mining, the stats output will by default be duplicated to add info for the ZIL mining. Some contexts might get confused by this if they are parsing the TRM outut or log files. To switch to the default output, add —stats_mode=single .
Hive OS – майнинг на Linux и мониторинг
Зарегистрируйте новую учётную запись в нашем сообществе. Это очень просто!
Войти
Уже есть аккаунт? Войти в систему.
Последние посетители 0 пользователей онлайн
- Ни одного зарегистрированного пользователя не просматривает данную страницу
Similar Topics
ФБР ликвидировало международную сеть вымогателей Hive
Hive Blockchain тестирует добычу различных монет с помощью видеокарт
Hive Blockchain в мае увеличила хэшрейт оборудования на 8%
Майнинговая компания Hive Blockchain приобретает чипы Intel для майнинга
Hive Blockchain закупит еще 4 000 ASIC-майнеров у Canaan Creative
- Ответов 4.2т
- Создана 3 Nov 2017, 02:23
- Последний ответ 26 Dec 2022, 14:39
Топ авторов темы
HaloGenius 341 постов
HiveOS 249 постов
LavA 193 постов
shost58 161 постов
Популярные дни
Популярные посты
HiveOS
3 Nov 2017, 02:23
Сервис мониторинга и операционная системя для майнинга. Мониторинг, управление, возможность разгона. Официальный сайт — https://hiveos.farm Установленные майнеры Claymore Dual
shabbat
2 Jan 2019, 11:13
@ZevSuk вопрос — если все так плохо, почему здесь? пусть вырабатывают весь оплаченный баланс на хайве(или у Вас, бесплатные "до 3х ферм". ), и переходи на другую ось. Выбор есть.
HiveOS
9 Mar 2018, 08:34
Мы вернулись к стабильной работе. Мы сделали много оптимизаций по коду и провели ряд апгрейдов на серверах. Много времени занял поиск истинной причины проблемы и окончательно выявилась проблема в драй
Видеокарта NVIDIA GTX 1080: хешрейт на эфире и производительность карты в майнинге других криптовалют


Разгон – это принудительное повышение характеристик оборудования для увеличения его эффективности. В случае с видеокартой её мощность напрямую зависит от двух параметров: тактовой частоты графического процессора и тактовой частоты видеопамяти. Именно их мы сегодня с вами и попробуем разогнать.
Отдельное слово хочется сказать про мощность и блок питания. Видеокарта является самой прожорливой составляющей ПК с точки зрения расходования мощности. Если в случае с разгоном процессора его энергопотребление остается фактически на том же уровне, то с видеокартой ситуация в точности да наоборот, энергопотребление, хоть и не намного, но возрастает (сложно назвать конкретные числа, все зависит от модели и разгонного потенциала вашей видеокарты). Отсюда и следует вывод, что блок питания необходим несколько мощнее, чем заявлено в рекомендации к GPU.
Часто спрашивают: Может ли видеокарта сгореть при разгоне? Ответ: Нет, если не повышать напряжение, подаваемое на графический процессор. В случае сбоя, карточка просто сбросит все частоты до базовых значений и продолжит работать.
Еще один вопрос, который, как я считаю, необходимо прояснить перед началом: почему видеокарты от разных производителей работают на разных частотах и стоят по разному, ведь они все от Nvidia? Общая картина здесь выглядит следующим образом. Одно из направлений компании Nvidia – разработка и создание графических процессоров.
Другие компании типа MSI, Asus, Gigabyte, Zotac, Palit и др. покупают уже, как правило, готовую, разработанную компанией Nvidia видеокарту и модифицируют ее по своему усмотрению. Кто-то понижает тактовую частоту ядра, кто-то наоборот разгоняет, кто-то меняет разъемы для подключения устройства вывода (монитора), кто-то делает прочие модификации.
В итоге мы получаем, что одна и та же модель видеокарты может стоить по-разному и работать на разных базовых частотах. Отсюда следует вывод, что оверклок – дело сугубо индивидуальное и зависит конкретно от вашей модификации. Для приблизительного понимания производительность разных моделей GPU вы можете воспользоваться калькулятором производительности и доходности от WhatToMine.
RaveOS предлагает Вам широкий функционал по оптимизации и разгону майнинг ригов
Есть возможность «отложенного» разгона, который применится, после старта майнера, через определенное время, заданное Вами . Система считывает максимум две команды oc.
Одна, простая, применяться до начала майнинга другая с опцией -sleep (отложенный оверклок) Для того чтобы воспользоваться этой функцией, Вам необходимо в Set задать: oc -sleep=X … где X — количество секунд после запуска майнера по прошествии которого применятся параметры

Например: “oc -sleep=30 -cclk=123 -mclk=990 -tt=55 ”.
Частота ядра и памяти, целевая температура применятся по прошествии 30 секунд , после старта майнинга.
Тесты и сравнение с Radeon HD 4870
В блоге «Выбираем оптимальную ОС для игр на видеокарте с 1 ГБ видеопамяти — Windows 7 или Windows 10» я протестировал Radeon HD 4870 в нескольких играх, и это даст возможность сравнить ее результаты с GeForce GT 1030, ведь все параметры системы остались неизменными. А производительность Radeon HD 4870 схожа с огромным пластом видеокарт: Radeon HD 5770, Geforce GTS 450, Radeon HD 7750 и GeForce GTX 550 Ti.
Давайте начнем с Mafia II с минимальными настройками в 1080p, ведь средний FPS в 24.8 на Radeon HD 4870 был неиграбельным. GeForce GT 1030 выдала 46.1 FPS в стоке и 52.7 FPS в разгоне, в два раза обогнав Radeon HD 4870. Разгон повысил средний FPS на 14%, что очень неплохо!

В бенчмарке Far Cry 2, с пресетом VeryHigh, GeForce GT 1030 выдала 110 средних FPS в стоке, а разгон повысил результат до 123 FPS, что составляет 11%. Radeon HD 4870 в этом тесте набирала всего 61.3 FPS, то есть мы опять имеем почти двукратный прирост.

В бенчмарке S.T.A.L.K.E.R — Call Of Pripyat на низких настройках, в 1080p и с режимом DX10 GeForce GT 1030 в разгоне дала прирост около 11%. Radeon HD 4870 в этом тесте отстает на 51%.

Во встроенном бенчмарке стратегии World in Conflict разгон принес GeForce GT 1030 12% среднего FPS, а Radeon HD 4870 отстает по этому параметру на 38%.

Внимание «oc -sleep … » и «oc … » — это две разные команды.
Отложенный оверклок oc -sleep
Вы можете применять оверклок через поле Execute. (кнопка Set на вкладке Tuning):
Доступные аргументы для “oc -sleep …”:
-sleep= — Количество секунд после запуска майнера, через которое нужно применить данный оверклок Пример: -sleep=40 AMD -cvddc= — Вольтаж ядра в mV (только для AMD). Пример: -cvddc=800 -mvddc= — Вольтаж контролера памяти в mV (только для AMD). Пример: -mvddc=800 -socvddmax= — Максимальный вольтаж SOC в mV (только для Navi10, Navi14). Пример: -socvddmax=800 -gfxvddmax= — Максимальный вольтаж GFX в mV (только для Navi10, Navi14). Пример: -gfxvddmax=800 -socclkmax= — Максимальная частота SOC в Mhz (только для Navi10, Navi14). Пример: -socclkmax=800 -gfxclkmax= — Максимальная частота GFX в Mhz (только для Navi10, Navi14). Пример: -gfxclkmax=800 NVIDIA -cclk= — Частота ядра в Mhz (для Nvidia — смещение частоты). Пример: -cclk=100 -mclk= — Частота памяти в Mhz (для Nvidia — смещение частоты). Пример: -mclk=1000 -pl= — Лимит потребления в ваттах (только для Nvidia). Пример: -pl=100
Пример: « oc -sleep=40 -cclk=123 -mclk=1100 »

Функционал оверклока oc
Вы можете применять оверклок через поле Execute. (кнопка Set на вкладке Tuning):
Команда всегда должна начинаться с « oc » Доступные аргументы для “oc …”:
-fan= — Скорость вращения вентиляторов (если автофан выключен). Пример: -fan=70 -fanmin= -минимально допустимое значение вентилятора при включенном автофан. Пример: -fanmin=0 -fanmax= -максимально допустимое значение вентилятора при включенном автофан.Пример: -fanmax=100 -tt= — Целевая температура (если включен автофан). Пример: -tt=65 -wh= — Вотчдог по хешрейту на уровне карты (h/s). Пример: -wh=30000000 (30Mh/s). Пример(40Mh/s): -wh=40000000 AMD -cvddc= — Вольтаж ядра в mV (только для AMD). Пример: -cvddc=800 -mvddc= — Вольтаж контролера памяти в mV (только для AMD). Пример: -mvddc=800 -socvddmax= — Максимальный вольтаж SOC в mV (только для Navi10, Navi14). Пример: -socvddmax=800 -gfxvddmax= — Максимальный вольтаж GFX в mV (только для Navi10, Navi14). Пример: -gfxvddmax=800 -socclkmax= — Максимальная частота SOC в Mhz (только для Navi10, Navi14). Пример: -socclkmax=800 -gfxclkmax= — Максимальная частота GFX в Mhz (только для Navi10, Navi14). Пример: -gfxclkmax=800 -ttm= — Целевая температура памяти для карт на чипах Vega/Navi (если включен автофан). Если установлено больше 0, -tt игнорируется! Пример: -ttm=75 -lp=1 — Позволяет снизить потребление на AMD RX 6xxx серии на 20-30W (только для Navi21, Navi22) NVIDIA -cclk= — Частота ядра в Mhz (для Nvidia — смещение частоты). Пример: -cclk=100 -mclk= — Частота памяти в Mhz (для Nvidia — смещение частоты). Пример: -mclk=1000 -pl= — Лимит потребления в ваттах (только для Nvidia). Пример: -pl=100 -fixclk= — устанавливает фиксированную частоту ядра на 20й, 30й сериях Nvidia (Экспериментальная опция! В некоторых случаях может помочь снизить потребление). Пример: -fixclk=800 -fixpstate=1 — отключение перевода драйверами CUDA и OpenCL карт в режим PState2. Аналог опции CudaForceP2State=off на Windows в Nvidia Inspector. !! ВНИМАНИЕ!! Глобальная настройка, применится для ВСЕХ карт (Экспериментальная опция! Включает возможность установки повышенных частот памяти) -led= — управление подсветкой логотипа на некоторых Nvidia картах. По-умолчанию: 0. Допустимый диапазон 0-100. Пример: -led=0 (выключен)
Пример: « oc -cclk=1070 -mclk=2050 -cvddc=780 -mvddc=800 -tt=65 -fan=80 »

Майнинг на Nvidia GeForce GTX 1070 8gb: сколько мегахешей выдает карта на других алгоритмах
На таких производительных GPU можно майнить не только эфир. Сколько мегахешей выдает видеокарта 1070 для других криптовалют? Мы составили таблицу хешрейта NVIDIA GTX 1070 (hashrate) для популярных алгоритмов на основе данных сайта whattomine.com. Цифры могут быть ниже тех, что заявлены в обзорах, так как производительность GPU напрямую зависит от производителя и настроек карты для майнинга.
Для видеокарт NVIDIA
GIGABYTE GTX 1070 TUNING (Core Clock: 150, MemoryClock: 700, Power limit: 133, Fan 75,) NVIDIA GTX 1080 TUNING (Core Clock: 20, MemoryClock: 1200, Power limit: 190, Fan 65, Target Temp 50) Set: oc -tt=50 T-rex miner: —mt 3 Gtx 1070ti: TUNING (Core Clock: -10, MemoryClock: 0, Power limit: 120, Fan 65,) SET
:
oc -sleep=20 -cclk=0 -mclk=1100 MSI 1080ti: TUNING (Core Clock: -10, MemoriClock: 0, Pover limit: 280, Fan: 50, Target Temp: 55) SET: oc -tt=55 oc -sleep=25 -cclk=129 -mclk=985 ————————————— TUNING: ( Core Clock 132 MemoriClock 0 Pover limit 0 Fan 50 Target Temp 55 ) Set : oc -fixpstate=1 -tt=55 T-Rex miner: -i 24 —mt 5 AORUS 1080ti: TUNING (Core Clock: -10, Power limit: 250) SET
:
oc -sleep=20 -cclk=100 -mclk=1100 ZOTAC GTX 1080ti: TUNING (Core Clock: -10, Memory Clock: 800, Power limit: 250) SET
:
oc -tt=55 oc -sleep=20 -cclk=105 -mclk=1100 EVGA GTX 1080ti: TUNING (Core Clock: -50, Memory Clock: 900, Power limit: 255) SET
:
oc -tt=50 oc -sleep=20 -cclk=100 -mclk=1100 ASUS GTX 1080ti: TUNING (Core Clock: -50, Memory Clock: 800, Power limit: 255) SET
:
oc -tt=56 oc -sleep=20 -cclk=109 -mclk=1118 MSI GTX 1660 Ti: TUNING ( Core Clock: -400, Memory Clock: 2260, Power limit: 70, Fan: 0, Temp: 50 ) MSI GTX 1660 SUPER: TUNING ( Core Clock: 0, Memory Clock: -1004, Power limit: 75, Fan: 50 ) Gigabyte GTX 1660 SUPER: TUNING ( Core Clock: 0, Memory Clock: -1100, Power limit: 80, Fan: 50 ) Nvidia GTX 1660 SUPER: TUNING ( Core Clock: 0, Memory Clock: -1090, Power limit: 85, Fan: 50 ) ASUS RTX 2060 SUPER: TUNING ( Core Clock: -670, Memory Clock: 2150, Power limit: 125, Fan: 40 ) Gigabyte RTX 2060 TUNING ( Core Clock: 100, Memory Clock: 2100, Power limit: 130, Fan 60, Target Temp: 60) SET: oc -fixclk=1150 -wh=30000000 -tt=57 ASUS GeForce RTX 2070 ROG Strix (micron) TUNING ( Core Clock: 0, Memori Clock: 1450, Pover limit: 130, Fan: 55, Target Temp: 55 ) SET: oc -fixclk=1050 RTX 3000: SET
:
oc -sleep=20 -mclk=2540 Gigabyte Eagle 3060 Ti: TUNING ( Core Clock -200 Memori Clock 2400 Pover limit 140 Fan 75 ) SET
:
oc -tt=60 oc -sleep=25 -mclk=3350 MSI GeForce RTX 3060 Ti TWIN FAN: TUNING ( Core Clock: -502, Power limit: 130, Fan 60, Target Temp: 60) SET
:
oc -wh=30000000 oc -sleep=20 -mclk=2505 Palit 3060 Ti Dual OC: SET
:
oc -pl=130 -cclk=-502 -wh=55000000 -fanmin=30 -fanmax=80 -tt=56 oc -sleep=60 -mclk=2550 Palit GeForce RTX 3060 Ti Dual: TUNING ( Core Clock: -500, Power limit: 135, Fan 60, Target Temp: 60) SET
:
oc -wh=30000000 oc -sleep=25 -mclk=2500 MSI RTX 3070 VENTUS 2X: TUNING (Core Clock: 0 , Memory Clock: 0, Power limit: 150, Fan: 50) SET: oc -tt=60 oc -sleep=20 -cclk=-500 -mclk=2800 Gigabyte RTX 3070: TUNING ( Core Clock: -200, Memory Clock: 0, Power limit: 135, Fan 60, Target Temp: 60 ) SET: oc -tt=60 oc -sleep=20 -mclk=1800 MSI RTX 3070: TUNING ( Core Clock: 0, Memory Clock: 2000, Power limit: 130, Fan 60, Target Temp: 55 ) SET
:
oc -tt=60 oc -sleep=20 -cclk=-500 -mclk=2800 Palit RTX 3070: TUNING ( Core Clock: -500, Memory Clock: 2400, Power limit: 130, Fan: 60, Target Temp: 50) ASUS TUF 3070 (Samsung) TUNING ( Core Clock: 0, Memori Clock: 2680, Pover limit: 120, Fan: 55, Target Temp: 55 ) SET: oc -fixclk=1150 ————————————————————————————- TUNING ( Core Clock: -100, Memori Clock: 1000, Pover limit: 120, Fan: 55, Target Temp: 55 ) SET: oc -fixclk=900 -sleep=30 -mclk=2750 MSI RTX 3080 TUNING ( Core Clock: 0, Memory Clock: 2700, Power limit: 180, Fan: 70, Target Temp: 50) Palit RTX 3080 TUNING ( Core Clock: 0, Memory Clock: 2700, Power limit: 235, Fan: 75, Target Temp: 50) ASUS RTX 3090: TUNING ( Core Clock: -300, Memory Clock: 0, Power limit: 325, Fan 70 ) SET
:
oc -sleep=20 -mclk=1400 MSI RTX 3090: TUNING ( Core Clock: -300, Power limit: 305, Fan 90 ) SET
:
oc -sleep=20 -mclk=2600
Разгон
Конечно же, я сразу же решил проверить разгонный потенциал видеокарты, и смог увеличить частоту чипа в MSI Afterburner на 200 МГц, а вот памяти — всего на 550 МГц.

Мне не повезло и у видеокарты оказались чипы памяти Micron. Чипы памяти Samsung дали бы лучшие результаты. Но прирост в 3Dmark 11 оказался заметным — 5573 очка или почти 9%, что позволило обогнать GeForce GTX 750 и приблизиться к результатам GeForce GTX 750 Ti.

Для видеокарт AMD
ASUS RX 470: TUNING: ( Core Clock: 1125, Memory Clock: 2000, Core voltage: 850, Memory voltage: 850, Fan 70, Target Temp:60 ) SET: amdmemtweak —REF 30 RX 580 Nitro+: TUNING (Core Clock: 1300, Memory Clock: 2200, Fan: 70) SET: amdmemtweak —REF 30 ATI Radeon RX 580: TUNING (Core Clock: 1200, Memory Clock: 2210, Fan: 70, Target Temp: 60) SET: amdmemtweak —REF 30 Gigabyte RX 5600 XT: TUNING: ( Core Clock: 1070, Memory Clock: 910, Core voltage:670, Memory voltage: 760, Fan 75, Target Temp: 0 ) SET: oc -mvdd=1280 -socvddmax=850 -socclkmax=950 Sapphire RX 5600 TX: TUNING: ( Core Clock: 1070, Memory Clock: 910, Core voltage:700, Memory voltage: 770, Fan 60, Target Temp: 0 ) SET: oc -mvdd=1280 -socvddmax=850 -socclkmax=950 PowerColor RX 5600 XT: TUNING: ( Core Clock: -100, Memory Clock: 0, Core voltage: 800, Memory voltage: 800, Fan 60,) SET: oc -sleep=40 -cclk=1100 -mclk=940 MSI RX 5600 XT: TUNING: ( Core Clock: -10, Memory Clock: 0, Core voltage: 700, Memory voltage: 0, Fan 0, Target Temp: 46 ) SET: oc -sleep=20 -cclk=1110 -mclk=930 Gigabyte 5700 XT: SET: oc -sleep=20 -mvdd=1270 -socclkmax=800 -gfxvddmax=700 atitool -i=[0] -VDDCR_SOC=0.74v Msi RX 5700 XT: TUNING: ( Core Clock: 0, Memory Clock: 0, Core voltage: 875, Memory voltage: 800, Fan 60,) SET: oc -ttm=75 oc -sleep=25 -cclk=1280 -mclk=900 -gfxvddmax=800 -mvdd=1300 -socclkmax=1050 PowerColor RX 5700 XT: TUNING: ( Core Clock: 1400, Memory Clock: 900, Core voltage: 850, Memory voltage: 0, Fan 60) Sapphire RX 5700 XT: SET: oc -gfxvddmax=800 -mvdd=1300 -socclkmax=1110 -ttm=95 oc -sleep=60 -mclk=940 -cvddc=775 -mvddc=775 Asus ROG Strix RX 5700 XT: TUNING: ( Core Clock: 1340, Memory Clock: 900, Core voltage: 712, Memory voltage: 700, Fan 50, Target Temp: 48 ) SET: oc -wh=51000000 -socclkmax=950 -mvdd=1250 Sapphire RX 6700 XT TUNING: ( Core Clock: 1200, Memory Clock: 1070, Core voltage: 630, Memory voltage: 630, Fan 57, Target Temp: 60 ) в SET: oc —wh=15000000 -ttm=60 -lp=1 AMD RX 6800: TUNING: ( Core Clock: 1275, Memory Clock: 1060, Core voltage: 680, Memory voltage: 690, Fan 85, Target Temp: 60 ) SET: oc -mvdd=1250 -socvddmax=850 -socclkmax=950 Sapphire RX 6800: TUNING: ( Core Clock: 1275, Memory Clock: 1060, Core voltage: 690, Memory voltage: 690, Target Temp: 60 ) SET: oc -wh=44000000 -socclkmax=950 -socvddmax=900 -mvdd=1250 -fanmin=21 -fanmax=85 AMD RX Vega 56: TUNING: ( Core Clock: 0, Memory Clock: 0, Fan 70, Target Temp: 50 ) SET: amdmemtweak —i [tid] —CL 20 —RAS 20 —RCDRD 11 —RCDWR 12 —RC 36 —RP 10 —RRDS 3 —RRDL 6 —RTP 5 —FAW 12 —CWL 8 —WTRS 4 —WTRL 9 —WR 14 —REF 65535 —RFC 216 oc -cclk=960 -mclk=900 -cvddc=766 -mvddc=766 -wh=44000000 atitool -i=[tid] -socclk=900 && sleep 1 && atitool -i=[tid] -vddio_mem=1.155 -vddcr_hbm=1.155 -0.8v=0.755 SET SAMSUNG
:
amdmemtweak —i [tid] —CL 20 —RAS 20 —RCDRD 13 —RCDWR 12 —RC 38 —RP 11 —RRDS 3 —RRDL 6 —RTP 5 —FAW 12 —CWL 8 —WTRS 4 —WTRL 9 —WR 14 —REF 65535 —RFC 248 oc -cclk=1200 -mclk=1106 -cvddc=850 -mvddc=850 -ttm=85 atitool -i=[tid] -vddio_mem=1.337 -vddcr_hbm=1.337 -0.8v=0.800 SET HYNIX
:
amdmemtweak —i [tid] —RAS 15 —RCDRD 12 —RCDWR 12 —RC 34 —RP 13 —RRDS 0 —RRDL 0 —faw 12 —REF 65535 —RFC 216 oc -cclk=1000 -mclk=940 -cvddc=775 -mvddc=775 -wh=44000000 atitool -i=[tid] -socclk=960 && sleep 1 && atitool -i=[tid] -vddio_mem=1.23 -vddcr_hbm=1.23 -0.8v=0.755
Все, выше предложенные, примеры были получены от участников телеграмм чата @raveOSchat
Если Вы хотите поделиться своими, удачными, параметрами разгона пишите на почту
Характеристика RTX A2000
| Характеристики GPU | NVIDIA RTX A2000 |
| Объем видеопамяти | 6 ГБ | 12 ГБ GDDR6 с коррекцией ошибок (ECC) |
| Разъемы дисплея | 4 x mini DisplayPort 1.4 |
| Максимальное энергопотребление | 70 Вт |
| Шина передачи данных | PCI Express Gen 4 x 16 |
| Форм-фактор | Высота 5,08 см, длина 15,24 см, ширина в два слота |
| Охлаждение | Активное |
| Поддержка VR | Да |
Характеристики RTX A2000
Карта может быть с 6 Gb и 12 Gb видео памяти. Память быстрая GDDR6.
TeamRedMiner: Команды и Параметры для майнинга
Аргументы командной строки — это аргументы, которые указываются после имени программы в системной командной строке, и значения этих аргументов передаются вашей программе во время выполнения.
Использование: teamredminer.exe -команда1 -команда2 -команда3
Пример для Ravencoin:
teamredminer.exe -a kawpow -o stratum+tcp://rvn.2miners.com:6060 -u RKAeArXkWLNERjWo5YF3R1xFnYCwKf11sX.worker_name -p x
Полный список параметров:
Алгоритм
—algo или краткий синоним этой команды -a — выбирает алгоритм майнинга.
Важно! Используйте либо длинный синоним, —algo= либо короткий -a . Вам не нужно использовать вместе два варианта одной и той же команды.
Дальнейшие команды будут разделены запятыми. Сначала короткий синоним, а затем длинный. Не забудьте использовать только один вариант.
Доступные на данный момент алгоритмы:
teamredminer.exe -a ethash
URL пула
-o — устанавливает URL пула и ПОРТ пула. В настоящее время поддерживаются протоколы stratum+tcp и stratum+ssl URL-адреса.
В этом примере URL-адрес ethash.poolbinance.com и порт 8888 . Значения должны быть разделены знаком :
Каждый раз, когда указывается эта опция, будет запускаться новая конфигурация пула.
Параметры для каждого пула (например -u , -p ) необходимо будет снова явно указывать для каждого нового пула. (См. пример файла start_multipool.sh/bat ).
Стратегия нескольких пулов для майнера устанавливается с —pool_strategy опцией.
SSL/TLS (для продвинутых пользователей)
Также имеется специальная поддержка расширенных настроек SSL/TLS, когда вам нужно передать имя хоста SNI конечной точке SSL. Например, это необходимо для конечных точек SSL, которые действуют как интерфейсы для нескольких хостов и должны знать, для какого из них предоставить сертификат. В таких случаях используйте следующий формат:
Это подключится к pool.tunnel.com:3333 , но передаст pool.realhostname.com в качестве имени хоста SNI на этапе подтверждения SSL. Разумеется, два имени хоста также могут быть идентичными.
Имя пользователя (логин пула) или адрес кошелька
-u , —user=USERNAME — устанавливает имя пользователя или адрес кошелька для авторизации майнинг-пула.
Если на пуле нет регистрации, то вместо логина нужно указать адрес кошелька.
Пароль (необязательно)
-p, —pass=PASSWORD — устанавливает пароль для авторизации пула.
Имя воркера (worker name)
Воркер — это название вашего виртуального “рабочего”. Это название указывается для простоты отслеживания статистики.
.worker — установите простое имя воркера для отслеживания вашего рига (фермы) в пуле. Имя работника указывается после знака wallet_address и перед ним ставится точка.
Минимальная настройка для запуска должна обеспечить только:
- адрес пула,
- адрес кошелька и
- имя воркера.
Просто скопируйте и измените адрес кошелька на адрес вашего кошелька. Это пример для Ethermine:
teamredminer.exe -a ethash -o stratum+tcp://eu1.ethermine.org:4444 -u 0x360d6f9efea21c82d341504366fd1c2eeea8fa9d.worker_name -p x
Список аргументов командной строки
-h , —help Display help message and exit.
—debug Enables debug log output.
—disable_colors Disables console output colors.
—force_colors Forces console color output even if the terminal does not seem to support them.
—api_listen=IP:PORT Enables the sgminer compatible api. IP:PORT is optional. If present, the IP:PORT combo decides the interface(s) and port to listen to. Default is 127.0.0.1:4028 . For external access, use e.g. 0.0.0.0:4028 . It’s also valid to only specify the port, e.g. 4029 .
—cm_api_listen=IP:PORT Enables the claymore compatible api. IP:PORT is optional. If present, the IP:PORT combo decides the interface(s) and port to listen to. Default is 127.0.0.1:3333 . For external access, use e.g. 0.0.0.0:3333 . It’s also valid to only specify the port, e.g. 3334 .
—cm_api_password=PSW Sets the required password for the CM compatible api interface.
Журнал (Logs)
—log_file(=FILENAME) Enables logging of miner output into the file specified by FILENAME . If no filename is provided, the miner will log to trm_<algo>_<yyyymmdd_hhmmss> .log in the current working directory. If the log file already exists, the miner will append.
-l, —log_interval=SEC Set the time interval in seconds for averaging and printing GPU hashrates. SEC sets the interval in seconds, and must be > 0.
—log_rotate=SZ[,CNT] Enables log rotation. The SZ value sets the log size after which a new log file will be created. The SZ value supports the suffixes ‘k’, ‘M’, and ‘G’ and will multiply the value by 1024 , 1048576 , and 1073741824 respectively.
The optional CNT value sets the maximum number of old log files to keep. For example the option —log_rotate=4M,16 will cause the miner to switch to a new log file once the current log file exceeds 4194304 bytes in size, and the miner will keep the last 16 such files and delete older ones.
—short_stats Disables the full gpu state output in each hashrate output, like it was before 0.7.10.
—long_timestamps Enables microsec timestamps in the logs instead of seconds only.
—high_score Enables printouts of the top 15 shares found since miner start in the stats output.
—pool_debug Logs all pool traffic.
Комиссия (DevFee)
—dev_location=LOC Selects a specific location for the dev fee connection. Only use this if you see continuous dev fee connection issues reported by the miner. The connection management normally works well in all locations.
Available options are:
- world — Anywhere in the world except for mainland China.
- cn — Mainland China.
- non-gcp — Countries with blocked access to Google Services (e.g. Iran, Cuba).
Производительность
—enable_compute (Windows only) Enables compute mode and disables crossfire on necessary gpus.
—restart_gpus (Windows only) Restarts all configured gpus before mining, i.e. disable+enable PCI device.
—uac (Windows only) Enable privilege escalation when the miner runs tasks like restarting gpus.
You can always avoid this by running the miner directly as Administrator. This will trigger the standard Windows escalation prompt, so you have to be available to click ‘Yes’.
If this is not enabled, tasks that require Administrator privileges will fail when the miner is running under a basic user account.
Note: this might not be enabled for all algos.
—allow_dup_bus_ids Allows multiple gpus using the same pci bus id. This should only be used for Radeon Pro Duo cards and similar hardware, it’s normally an indication of a broken OpenCL environment.
Подключение к пулу
-o, —url=URL Sets the pool URL. Currently stratum+tcp and stratum+ssl URLs are supported.
- Each additional time this option is specified will start a new pool config.
- Per-pool options (such as -u, -p) will need to be explicitly specified again for each new pool. (See the example start_multipool.sh/bat file)
- The multi-pool strategy for the miner is set with the –pool_strategy option.
There is also special support for advanced SSL/TLS setups where you need to pass a SNI hostname to the SSL endpoint. For example, this is necessary for SSL endpoints that act as frontends for multiple hosts and need to know which one to provide a certificate for. In such cases, use the following format:
This will connect to pool.tunnel.com:3333 but pass pool.realhostname.com as the SNI hostname in the SSL handshake phase. The two hostnames can of course be identical as well.
-u , —user=USERNAME Sets the username for pool authorization.
-p , —pass=PASSWORD Sets the password for pool authorization.
—pool_force_ensub Forces an extranonce subscribe request for supported pools unknown to the miner.
—pool_no_ensub Prevent miner from sending extranonce subscribe request to the pool.
—pool_broken_rpc Tells the miner to only allow a single outstanding rpc request on the pool connection. This is a work-around for pools that violate the json rpc specification regarding rpc IDs.
—pool_ratio=RATIO Sets the hashrate ratio between pools when using multiple pools with the the load_balance or quota pool strategies (see —pool_strategy ). By default all pools use the ratio value 1. For example, using this option with a value of 2 on just one pool will make that pool receive twice the hashrate as the other pools since their ratio will still be the default value of 1.
Глобальные опции пула
—pool_connect_TO=SEC Set the time-out for attempting to connect to a pool. SEC is the time to wait in seconds. Default is 10.
—pool_rpc_TO=SEC Set how long the miner will wait for an unanswered RPC to the pool. After this time, the miner will reconnect to the pool. SEC is the time to wait in seconds.
Default is 60.
—pool_max_rejects=N If a pool rejects N shares in a row, the pool connection is reset. This is to prevent against pools that invalidates mining sessions without disconnecting the user.
Default value is 5.
—pool_share_limit_ms=N If a pool takes longer than N ms to accept or reject a share, kill the current connection and reconnect. This is intended for pools that often get issues with some of their servers, but reconnecting means being load-balanced to a different and hopefully better server. Default value is no timeout.
—pool_strategy=STRAT Sets the strategy for selecting pools when running with multiple pools.
The available values are:
- priority,
- load_balance,
- quota, and
- min_epoch.
The default is priority.
- priority : The miner will use pools in the order they are listed, only moving on to the next pool if the previous cannot establish a connection.
- load_balance : The miner will evenly balance the hashrate across all currentlyconnected pools. The ratio of hashrate between pools can be set with —pool_ratio .
- quota : The miner will evenly balance the total hashes completed across all pools. If a pool disconnects and later reconnects, the miner will move hashrate to the pool until the total hashes for each pool is balanced.
The ratio of hashrate between pools can be set with —pool_ratio .
- min_epoch : ETH + ZIL switching strategy. The miner will always mine the lowest epoch among all connected pools, and in case of a tie, the first connected pool.
Therefore, specify your ETH mining pool as the first/primary pool, then the ZIL pool as the second pool. You can also use ‘eth_zil’ as the name for this strategy.
—no_ntime_roll Prevents the miner from rolling ntime in the block header, only using the value provided by the pool. This needs to be enabled for some pools when mining x16rt .
—no_stale_submit Prevents the miner from submitting shares that are not for the most current pool job.
Опция выбора видеокарт
—platform=INDEX Sets the index of the OpenCL platform to use. If not specified, platform will be auto-detected. Linux with multiple platforms is only supported using no —platform arg but instead adding —bus_reorder .
-d , —devices=DEVLIST Sets gpu devices to use from detected list. DEVLIST should be a comma-separated list of device indices, e.g. -d 0,1,2,4. If not specified, alldevices on the platform(s) will be used. NOTE: by default the devices are orderedby pcie bus ordering. Use —list_devices to show indices.
—init_style=1/2/3 Specified the init style (1 is default):
- One gpu at the time, complete all before mining.
- Three gpus at the time, complete all before mining.
- All gpus in parallel, start mining immediately.
—pcie_fmt=FORMAT Sets print format for pcie bus numbers. The accepted values for FORMAT are either hex or dec . The default is dec for windows and hex for linux.
—bus_reorder Reorders the detected or specified devices after their pcie bus id. If noplatform is specified, devices will be collected from all detected AMD OpenCLplatforms. Note: As of version v0.7.0 this is the default behavior.
—opencl_order Orders the detected or specified devices in the order OpenCL presents them.
—list_devices Lists the available devices for the detected or specified platform and exits immediately. Bus reordering will be implemented in the displayed order.
—nr_cu_override=X,Y. Overrides the nr compute units per gpu as presented by the OpenCL API. This is primarily useful for Vega 64s flashed with 56 biosed and where the driver is reporting 56 CU instead of the true count. Provide a comma-separated list of the override CU count per gpu as value for the argument.
You can skip gpus and do not need to provide values for all gpus in the rig. Example for a mixed rig of two Vegas at index 1 and 3 and two other gpus: –nr_cu_override=,64,,64. You can verify your argument by also adding —list_devices before mining.
Варианты управления разгоном / напряжением (только для Windows, BETA функциональность)
The miner has basic functionality for setting core and mem clks and their respective voltage, as well as selecting between the win driver’s built-in timings. For each available argument below, you enumerate values for gpu(s) in the rig in a comma-separated list.
Some arguments are not used for certain gpus. You can skip gpus in the list.
The miner always sets and uses the highest p-state for both core and mem for GCN gpus (Polaris, Vega). Please note that Rx Vega gpus must have a powerplay table modification of the mem p2 state before being able to run a voltage lower than 900mV. Moreover, Big Navi gpus also still need to use e.g. MorePowerTool to make powerplay table modifications, for example for enabling setting a lower voltage. The miner might add support for powerplay table-related functionality in the future.
—clk_debug Enable start-up log printouts related to setting clocks/voltages/timings.
—clk_core_mhz=MHZ1,MHZ2. Sets the core clk per gpu in MHz.
—clk_core_mv=MV1,MV2. Sets the core voltage per gpu in mV.
—clk_mem_mhz=MHZ1,MHZ2. Sets the mem clk per gpu in MHz.
—clk_mem_mv=MV1,MV2. Sets the mem voltage per gpu in mV. Not used for Navi or Big Navi gpus.
—clk_timing=V1,V2. Selects between the driver’s available mem timing sets. Not available on all gpus and drivers.
Example of a partial command line for a four gpu system where with a Rx Vega 64, 580, 5700XT and 6800 mining ethash or similar. We only specify mem voltage for the Vega and 580, and only select a driver timing value for the Big Navi:
teamredminer.exe . —clk_core_mhz=1100,1000,1275,1000 —clk_core_mv=875,850,725,675 —clk_mem_mhz=1107,2100,1820,2130 —clk_mem_mv=875,850,, —clk_timing=. 1
Варианты управления вентилятором
—fan_control(=CFG1,CFG2. ) This argument enables gpu fan control by the miner. TRM supports auto-adjusting the gpu fan speed(s) based on core, junction and/or mem temp.
We also support setting a static fan speed in percent.
Each gpu type has a fan configuration that will be used by default. We support both overriding the default configuration per gpu type as well as setting a specific config per gpu in the rig.
A fan config consists of (max) six values, separate by the ‘:’ (colon) char. The values are: core target temp, junction target temp, mem target temp, initial fan speed in percent, min fan speed in percent, max fan speed in percent. Any value can be left empty.
These are a few examples:
- ::70:50:25 Target mem temp to 70C, start fan at 50% speed, min fan speed 25%.
- 55. 20:80 Target core temp to 55C, start fan at default configuration’s speed, always keep fan between 20% and 80%.
- 55::75:80 Adjust fan so that core temp is <= 55C and mem temp is <= 75C, start fan at 80%.
- . 100 Set static fan speed to 100%, never adjust based on temps.
The fan configuration used for a gpu is derived in the following precedence order:
- The —fan_control argument was passed a list of configurations and included an entry for gpu X.
- The default fan configuration for this gpu type was overridden with a —fan_default_<type>=. parameter.
- Use the built-in default fan configuration for this gpu type.
In the list above, if the chosen configuration is missing the start value for the fan the setting from the next configuration is used.
NOTE: fan support is a beta feature and will not work better than the support the drivers provide. For example, many times the drivers under linux don’t allow forcing a fan to 100% using the sysfs pwm support.
—fan_default_polaris=CFG Set the default config used for all Polaris gpus (450/460/550/560/470/480/570/580/590).
The built-in default is 55. 50 for 55C core temp and fan starting at 50%.
Note: this setting is also reused for Tonga gpus.
—fan_default_vega=CFG Set the default config used for all Vega gpus (Vega 56/Vega 64).
The built-in default is 55::70:50 for 55C core temp, 70C mem temp and fan at 50%.
—fan_default_vega2=CFG Set the default config used for all Radeon VII gpus.
The built-in default is 70::75:80 for 70C core temp, 75C mem temp and fan at 80%.
—fan_default_navi=CFG Set the default config used for all Navi (Navi10).
The built-in default is 60::80:70 for 60C core temp, 80C mem temp and fan at 70%.
—fan_default_big_navi=CFG Set the default config used for all Big Navi (Navi21).
The built-in default is 50. 70 for 50C core temp and fan at 70%. The reason for not including mem temp is a missing sensor in the Windows ADL library.
—fan_debug Enable log printouts related to adjustments.
Параметры сторожевого таймера
—no_gpu_monitor Disables the ADL (Windows) or sysfs (Linux) GPU monitor for temperature and fan speed.
—temp_limit=TEMP Sets the core temperature at which the miner will stop GPUs that are too hot.
Default is 85C. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the listis used.
—temp_resume=TEMP Sets the core temperature below which the miner will resume GPUs that were previously stopped due to the core temperature exceeding limit.
Default is 60C. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the list is used.
—mem_temp_limit=TEMP Sets the mem temperature at which the miner will stop GPUs that are too hot.
Default is not enabled. Only used if the gpu provides a mem temperature sensor.
Gpu-specific values can be provided using a comma-separated list, one value per gpu.
If a gpu doesn’t have a defined value, the first value in the list is used.
—mem_temp_resume=TEMP Sets the mem temperature below which the miner will resume GPUs that were previously stopped due to mem temperature exceeding limit.
Default is not enabled. Only used if the gpu provides a mem temperature sensor. Gpu-specific values can be provided using a comma-separated list, one value per gpu. If a gpu doesn’t have a defined value, the first value in the list is used.
—watchdog_script(=X) Configures the gpu watchdog to shut down the miner and run the specified platform and exits immediately. The default script is watchdog.bat/watchdog.sh in the current directory, but a different script can be provided as an optional argument, potentially with a absolute or relative path as well.
—watchdog_test Tests the configured watchdog script by triggering the same action as a dead gpu after
20 secs of mining.
—watchdog_disabled Forces the watchdog to not execute. Can be used to disable the watchdog in mining os that always run with the watchdog enabled.
Ethash опции
—eth_config=CONFIG Manual ethash configuration for the miner. CONFIG must be in the form [X][M][L] .
- The [M] value selects the mode which can be ‘A’,’B’, or ‘C’.
- The B mode uses additional memory and will only work on 8+GB cards.
- The C mode uses additional memory and will only work on 16+GB cards, such as the VII, with a correctly configured system. See the ETHASH_TUNING_GUIDE.txt for more details.
- The [L] value selects the intensity and it’s range will depend on the GPU architecture.
- The [X] prefix is optional and is Navi/Big Navi only, it enables more mem operations and leads to a lower tuning [L] value. It can be beneficial whenever the auto-tuner repeatedly hits a value close to the max possible tuning value for the gpu.
Both values are optional, but if [L] is specified, [M] must also be specified.
- —eth_config=A
- —eth_config=B750
- —eth_config=XB
CONFIG can also be a comma separated list of config values where each is applied to each GPU.
Any gpu that does not have a specific config in the list will use the first config in the list.
—eth_variant_mode=X This argument controls activation of the ethash changes for ETC from epoch 390 as described in ecip-1099.
The following modes are available:
pool — Default mode. Only activates if the pool sends an algo flag containing etchash.
Once this flag is seen, all pool jobs will be assumed to be etchash unless another.
algo flag containing ethash is received.
etchash — Etchash mode. Epoch >= 390 will be assumed to be etchash, lower epochs ethash. Pool algo flags are not used.
deduce — Ignore pool algo flags and only apply a heuristics based on the current system time and known heights and times for ETC and ETH. This mode should work as a generic approach when ETH reaches epoch 390 in Jan 2021. The system clock needs to be correct.
It should also handle any profit switching setups that switch freely between ethash and etchash jobs by proxying underlying pools.
auto — As long as the pool hasn’t passed an algo flag, use deduce mode. When an algo flag is seen, switch to pool mode.
ethash — Forced ethash mode. Never apply ecip-1099.
force_etc — Forced etchash mode. Always apply ecip-1099 rules. Use for ETC testnet mining.
—eth_aggr_mode Enables automatic use of the ‘B’ mode for all Polaris 8GB cards, unless they have a different config provided by the —eth_config argument. This is the same thing as manually setting all Polaris 8GB gpus in the rig to ‘B’ mode using —eth_config .
For most gpus, this adds 0.1-0.2 MH/s of hashrate.
NOTE: 20-25% of rigs becomes less stable in this mode which is the reason it isn’t the default mode. If you experience dead gpus, you should remove this argument and run the gpus in the ‘A’ mode.
—eth_stratum_mode=MODE Sets a fixed stratum mode for ethash pools.
By default the miner will attempt to automatically determine the type of stratum the pool supports and use that mode. This automatic detection can be overriden by specifying this option. The MODE can be set to one of the following options: stratum, nicehash, ethproxy.
—eth_worker Set the worker id that will be sent to pool. This only applies to pools with ethproxy stratum mode.
—eth_hash_report=X Controls hashrate reports to the configure pools. This value is applied for all pools.
- default — let the miner decide based on stratum protocol used for each pool.
- force — always send hashrate reports, even if the pool rejects them.
- on — send a first hashrate report, disable for any pool that rejects the message.
- off — never send hashrate reports.
—eth_epoch Tests a specific ethash epoch. NOTE: you still need to provide a pool as if you were mining, but no shares will be submitted. Simulated mining only.
—eth_alloc_epoch=N Allocates enough memory for the given epoch from the start. The miner will try to allocate more if it needs to later during mining. It’s recommended for rigs with one or more 4GB cards to test and set this to the max possible value to avoid reallocations at epoch switches. Optimal Linux rigs should be able to handle epoch 380, Windows rigs a little less (373-374).
—eth_dag_buf=X,Y. The miner can allocate a single or dual buffers for the DAG. For now, the default is DUAL buffers, which matches the behavior in all recent TRM releases. However, a single buffer is slightly better, leading to a small power save for all gpu types. Only recent drivers support single large allocations larger than 4GiB, typically from Adrenalin 20.9.1 and amdgpu-pro 20.x. The miner can automatically use single buffer mode when possible using this argument, as well a force single or dual buffers per gpu.
Supported values are
- A(uto),
- S(ingle),
- D(ual).
You can enumerate a comma-separated list for all gpus in the rig, or a single value for all gpus. A gpu that does not have a value in the comma-separated list will use the first value. Hence, to enable auto mode for all gpus, pass —eth_dag_buf=A NOTE: 4GB gpus will be forced to use dual buffers.
—eth_big_mode_adjust=X,Y. When using B- or C-modes, the miner runs better the more vram it can allocate. Unfortunately the drivers aren’t accurate reporting how much memory it’s possible to allocate, especially on Windows.
The miner will use a safe conservative number of 256MiB (Linux) and 512MiB (Windows) as an offset from the available vram size. If you want change this number, you can do so using this argument by providing.
a comma-separated list with values for one or more gpus. Values for gpus not running B/C-mode will be ignored. If a gpu doesn’t have a value in the list, the first provided value is used instead.
The allowed interval is [-64, 2048]. The higher number, the less vram is allocated on the gpu.
—eth_4g_max_alloc=X,Y. This argument allows mining on 4GB gpus after they no longer can store the full DAG in vram.
You pass either the max epoch to allocate memory for, or the raw nr of MB to allocate. You can provide a single value that applies to all 4GB gpus in the rig, or use a comma-separated list for specifying different values per gpu. Values for non-4GB gpus are ignored.
—eth_dag_slowdown=N Slows down the DAG generation. Pass a single digit 0-9. 0 means no slowdown (<= 0.7.9 behavior), 1 means minimal slowdown, 9 means max. Default value: 4 for a slight slowdown.
—eth_stagger Enables staggering of gpus when building a new DAG. This is more lean on PSUs that don’t like going from 0-100% load on all gpus at the same time.
—eth_no_stagger Disables –eth_stagger. Already the default behavior from 0.7.18. Argument kept for backwards compatibility only.
—eth_ramp_up Adds ramping up the intensity on all gpus after a DAG build, gpu disable/enable or network outage. Can help rigs with crashes right between the DAG build and starting mining.
—eth_no_ramp_up Disables —eth_ramp_up . Already the default behavior from 0.7.18. Argument kept for backwards compatibility only.
—eth_direct_abort Uses a different mechanism to abort ongoing gpu jobs. Recommended for Vegas in ROCm environments to minimize stale shares. Will apply to Vega and Polaris gpus in the rig only.
—eth_dag_alloc_patch Some motherboards with outdated bios can see hw errs typically on the first or last gpu in the system.
Use this argument to force a patched dag allocation strategy that most often solves the issue.
Upgrading your bios often solves the issue as well.
—eth_hashwatch(=M,M) Defines a min/max watchdog hashrate in MH/s expected when gpus are hashing. If a GPU falls outside of this range for too long it will be considered faulty and the watchdog will be triggered. The default min/max values are 2 MH/s and 150 MH/s.
To activate with default values, use —eth_hashwatch . To set your own values, use e.g. —eth_hashwatch=1.25,60 . The same range is used for all gpus in the rig. A negative value for one side disables it, e.g. use —eth_hashwatch=-1,1000 to handle gpu resets that result in huge fake hashrates but no minimum check.
—eth_dag_cache(=EPOCH) Enables saving eth DAGs from jobs with different epochs to prevent having to rebuild them in the future if jobs with the old epochs are received again. At most one DAG will be saved if GPU memory space allows. This is useful for switching pools such as eth+zil mining.
If you want to prebuild a certain epoch immediately at startup, add the optional value. Eth+zil switching miners should use —eth_dag_cache=0 . Only ethash (and not etchash) epochs can be prebuilt at this time.
—eth_dag_cache_resv=MEM Sets the amount of GPU memory the miner will attempt to leave unused when running with DAG caching enabled (see –eth_dag_cache). The argument MEM is the amount of memory to leave unused in mebibytes. The default value is 256.
—eth_dag_cache_verify Enable dag cache read and verification after a finished dag build. This will detect situations where the dag cache had bit errors and the resulting dag is partially broken.
We have seen this happen increasingly on Vegas as the dag has grown bigger. When detected, a new buffer will be allocated for the dag cache and the dag build restarted.
—eth_no_4gb_kernels Disable the ethash 4GB kernels and always use the regular kernels that assume the DAG will always fit in available vram on all gpus.
This is useful when mining ETC or ethash coins at lower epochs than ETH since the regular kernels have a better performance profile.
—eth_micro_delay=VAL Navi gpus only: adds a delay (measured in microseconds) when reenqueueing work on the gpu(s).
Weaker PSUs driving many gpus can sometimes not handle the “slew rate” when multiple gpus happen to reenqueue work at exactly the same time. Setting this to e.g. 32 will smoothen out the transition from no load to 100% load enough to lower the slew rate on such rigs.
The typical indication of this issue is hard hangs where the rig becomes unresponsive requiring a power cycle to reboot, but it can also be regular gpu crashes. Valid values are 1-128. Not using this argument means no delay, value zero.
Progpow опции (kawpow, firopow)
—prog_config=CONFIG Manual progpow configuration for the miner. CONFIG must be in the form [M][L].
- The [M] value selects the mode which can be either ‘A’ or ‘B’.
- The ‘B’ mode typically results in better performance but is only available for
- Vega on linux and Navi (linux or windows).
- The [L] value selects the intensity and it’s range will depend on the GPU architecture.
Both values are optional, but if [L] is specified, [M] must also be specified.
- —prog_config=A
- —prog_config=B750
CONFIG can also be a comma separated list of config values where each is applied to each GPU. For example: —prog_config=A,B750,,A288
Any gpu that does not have a specific config in the list will use the first.
—prog_height=VALUE Sets a fixed block height for progpow algorithms for benchmarking purposes.
Note that using this option needs a pool connection but will not submit shares.
—prog_strict Forces miner to always generate strictly accurate kernels. By default the miner will generate relaxed kernels that use less computation power but can result in occasional invalid shares.
—prog_dag_slowdown=N Slows down the DAG generation. Pass a single digit 0-9. 0 means no slowdown (<= 0.7.9 behavior), 1 means minimal slowdown, 9 means max. Default value: 4 for a slight slowdown.
—prog_stagger See `–eth_stagger.
—prog_ramp_up See `–eth_ramp_up.
—prog_no_stagger See `–eth_no_stagger.
—prog_no_ramp_up See `–eth_no_ramp_up.
—prog_micro_tune=X,Y. This option enables a small retuning session for every new random code block. This is important for Polaris gpus to run at their max speed. For Vegas and Navis it usually does not improve performance. The default AUTO mode enables it for all Polaris gpus but disables it otherwise.
The only reason to disable it would be for stability purposes. The argument value is a comma-separated list of values, one per gpu. If a gpu is missing a value, the value for the first gpu is used. Please note that setting a manual prog_config will effectively disable the micro-tuner as well. Available values are:
-
- turn OFF progpow micro-tuning for this gpu.
-
- turn ON progpow micro-tuning for this gpu.
-
- let the miner decide if micro-tuning should be enabled (AUTO).
Cryptonight опции
—rig_id Set the rig identifier that will be sent to the pool. This is only used for cryptonight pools.
—cn_config=CONFIG Manual cryptonight configuration for the miner. CONFIG must be in the form [P][I0][M][I1][:xyz], where [P] is an optional prefix and [:xyz] is an optional suffix.
For [P], only the value of ‘L’ is supported for low-end GPUs like Lexa/Baffin. [I0] and [I1] are the thread intensity values normally ranging from 1 to 16, but larger values are possible for 16GB gpus.
[M] is the mode which can be either ‘.’, -‘, ‘+’ or ‘*’. Mode ‘.’ means that the miner should choose or scan for the best mode.
Mode ‘*’ both a good default more and should be used if you mine on a Vega 56/64 with modded mem timings.
The exceptions to this rule are small pad variants (cnv8_trtl and cnv8_upx2), they should still use ‘+’. For Polaris gpus, only the ‘-‘ and ‘+’ modes are available.
NOTE: in TRM 0.5.0 auto-tuning functionality was added, making manual configuration of the CN config modes unnecessary except for rare corner cases. For more info, see the tuning docs and how-to documents bundled with the release.
- —cn_config=15*15:AAA
- —cn_config=14-14
- —cn_config=L4+3
CONFIG can also be a comma separated list of config values where each is applied to each GPU.
Any gpu that does not have a specific config in the list will use the first config in the list.
—no_cpu_check Disables cpu verification of found shares before they are submitted to the pool.
Note: only CN algos currently supports cpu verification.
—no_lean Disables the CN lean mode where ramp up threads slowly on start or restart after network issues or gpu temp throttling.
—no_interleave=DEVS Lists gpu devices where CN thread interleave logic should be not be used.
The argument is a comma-separated list of devices like for the -d option.
Use this argument if some device(s) get a worse hashrate together with a lot of interleave adjust log messages.
—alloc_patch=DEVS Lists gpu devices that loses hashrate between TRM v0.4.5 and later versions. With this argument a simpler mem allocation strategy is used, and the old (higher) hashrate should be restored. Auto-tuning mode can still be used.
—auto_tune=MODE Enable the auto-tune mode upon startup. Only available for CN variants. MODE must be either NONE, QUICK or SCAN. The QUICK mode checks a few known good configurations and completes within 1 min. The SCAN mode will check all possible combos and will run for 20-30 mins. Setting MODE to NONE disable the auto-tune feature. The default mode is QUICK.
—auto_tune_runs(=N) Executes multiple runs for the auto tune, each time decreasing the unit of pads used -1 in one of the threads (15+15 -> 15+14 -> 14+14 -> 14+13 -> …). You can specify the explicit nr of runs or let the miner choose a default value per gpu type (typically 3-4).
—auto_tune_exit If present, the miner will exit after completing the auto-tuning process. This is helpful when you want to scan for optimal settings and then use the resulting command line arg printed by the miner.
—allow_large_alloc If present, and when the driver indicates there is enough GPU vram available, the miner will be more aggressive with the initial memory allocation. In practice, this option means that Vega GPUs under Linux will start the auto-tuning process at 1615 rather than 1614 or 15*15.
MTP опции
—allow_all_devices Some algos can’t be mined on e.g. 4GB gpus. Those gpus will be disabled automatically by the miner. This argument overrides this logic and allows mining on all specified or detected devices.
X16* опции
—hash_order=VALUE Sets a fixed hash order for algorithms like x16r for benchmarking purposes.
Note that using this option needs a pool connection but will not submit shares.
The standard benchmark hash order for x16r is —hash_order=0123456789abcdef .
Nimiq опции
—nimiq_worker=VALUE Sets the worker/device name for nimiq to pass to the pool(s).
—nimiq_no_proxy Disables the automatic Nimiq proxy executed as a separate process. This means that the host and port passed to the miner must be pointing to a proxy.
—nimiq_proxy=VALUE Overrides the default path to the Nimiq proxy. The default is trm_nimiq_proxy-win.exe. and trm_nimiq_proxy-linux in the current miner director.
—nimiq_port=VALUE Overrides the default local port (4444) used for the Nimiq proxy. This can be used if your system is already using port 4444 for some other tcp/ip service.
Verthash опции
—verthash_file=FILE Sets the filename to be used to load/store the verthash data file. If this option is specified when the verthash algo is used, the miner will attempt to load the verthash data from the file. If the file does not exist, the miner will generate the verthash data and then save it in the file for future use.
If this option is not specified the miner will generate the verthash data in system memory on every start.
—verthash_max_uploads=N Some motherboards have issues with all gpus in the rig uploading the verthash table at the same time. This argument limits the number of concurrent gpus that are uploading the table at the same time at startup. Allowed values are 1-32. The default value is 4.
Autolykos2 опции
—autolykos_mem_adjust=N Sets the amount of memory in MiB that the miner should leave unused when allocating GPU buffers for autolykos. The default value is 384 on linux and 512 on windows.
For GPUs with displays attached, the default is increased by 512. If dual mining with ZIL, the default value is increased by 1024. The option can also be provided with a comma separated list of values where each value is applied to each GPU. If an empty value is specified in the list, the default will be used for that GPU. If a value is not specified for a GPU it will use the first value in the list.
—autolykos_slowdown=N Adds a slowdown of the pad build process. Valid values are 0-100. The default is 0, no slowdown.
—autolykos_ignore_diff Ignores the difficulty sent by the pool and only uses the 256-bit target provided in jobs.
Some pools don’t follow the ERGO reference miner pool implementation, in which case this argument might help. NOTE: this will be applied to all pools.
ZIL dual mining опции
—zil_start or —zil Starts the ZIL dual mining config. Between this and the —zil_end marker , all arguments are applied to the ZIL mining rather than the primary algo. It’s expected that the primary algo has been set up in earlier arguments. The intention is that you can add a —zil . —zil_end configuration to any working TRM configuration algo and things will work out of the box.
This argument automatically sets a range of default settings you want to use for ZIL:
- Cached copy of the ZIL epoch 0 DAG.
- Adjustment of memory allocated for the primary algo to fit the ZIL DAG.
- Choose ethash A-mode for the ZIL mining.
- Use the standard faster kernels for 4GB gpus since the DAG is max 1GB.
The minimal working setup is to only provide a ZIL pool that is ok with the miner ignoring the primary coin jobs and only mines during the ZIL windows. This is an example for ezil.me:
—zil -o stratum+tcp://eu.ezil.me:5555 -u <eth wallet>.<zil wallet>.<worker name> -p x —zil_end
For more info, read the ZIL dual mining guide packaged with the TRM release.
—zil_end Marks that we’re done with the ZIL mining config and all following arguments are for the primary algo. This argument isn’t strictly necessary, but should be included for mining distros since the user has no guarantee what arguments will be added automatically at the end of the command line by the distro.
—stats_mode=single/dual When adding ZIL dual mining, the stats output will by default be duplicated to add info for the ZIL mining. Some contexts might get confused by this if they are parsing the TRM outut or log files. To switch to the default output, add —stats_mode=single .
Hive OS – майнинг на Linux и мониторинг
Зарегистрируйте новую учётную запись в нашем сообществе. Это очень просто!
Войти
Уже есть аккаунт? Войти в систему.
Последние посетители 0 пользователей онлайн
- Ни одного зарегистрированного пользователя не просматривает данную страницу
Similar Topics
Майнинговая компания HIVE намерена увеличить свою производительность до 6 EH/s
ФБР ликвидировало международную сеть вымогателей Hive
Hive Blockchain тестирует добычу различных монет с помощью видеокарт
Hive Blockchain в мае увеличила хэшрейт оборудования на 8%
Майнинговая компания Hive Blockchain приобретает чипы Intel для майнинга
- Ответов 4.2 тыс
- Создана 3 Nov 2017, 02:23
- Последний ответ 26 Dec 2022, 14:39
Топ авторов темы
HaloGenius 341 постов
HiveOS 249 постов
LavA 193 постов
shost58 161 постов
Популярные дни
Популярные посты
HiveOS
3 Nov 2017, 02:23
Сервис мониторинга и операционная системя для майнинга. Мониторинг, управление, возможность разгона. Официальный сайт — https://hiveos.farm Установленные майнеры Claymore Dual
shabbat
2 Jan 2019, 11:13
@ZevSuk вопрос — если все так плохо, почему здесь? пусть вырабатывают весь оплаченный баланс на хайве(или у Вас, бесплатные "до 3х ферм". ), и переходи на другую ось. Выбор есть.
HiveOS
9 Mar 2018, 08:34
Мы вернулись к стабильной работе. Мы сделали много оптимизаций по коду и провели ряд апгрейдов на серверах. Много времени занял поиск истинной причины проблемы и окончательно выявилась проблема в драй